AI resilience is an enterprise’s ability to keep AI-powered services working, safely and predictably, when a model, cloud region, API provider or supporting component fails or degrades. It combines architectural redundancy, graceful degradation, monitoring and tested recovery plans so that an AI outage does not become a business outage.
As AI moves into customer service, operations and decision support, its failure modes become business risks. This guide maps those failure modes, the patterns that contain them, and how to build and test a resilience plan.
How enterprise AI systems fail
AI failures are broader than traditional downtime. A service can be online yet unusable, or working well yesterday and quietly worse today.
| Failure mode | Example | Impact |
|---|---|---|
| Provider outage | An external model API becomes unavailable or rate-limits heavily | Dependent features stop working |
| Cloud or region failure | A region hosting GPUs or vector databases goes down | Serving and retrieval fail together |
| Capacity shortage | GPU capacity cannot meet a demand spike | Rising latency, timeouts, queued requests |
| Model change | A provider updates or deprecates a model version | Changed behaviour, broken prompts or output formats |
| Quality degradation | Retrieval data goes stale or inputs drift | Plausible but wrong answers |
| Dependency failure | Identity services, tool APIs or data pipelines fail | Agents stall or act on incomplete data |
The last three are particularly dangerous because they may not trigger traditional alerts. Detecting them depends on quality-aware AI observability, not just uptime checks.
Concentration risk adds another dimension. Many enterprises depend on a small number of model providers and cloud platforms for most of their AI capability, so a single incident can affect many applications at once. Mapping which services share which dependencies is the first step to reducing that exposure.
Core AI resilience patterns
Resilient AI architectures borrow from classic distributed systems design, adapted for the particular behaviour of models.
Multi-model fallback
Keep at least one tested alternative model for each critical use case, ideally on a different provider or on your own infrastructure. A routing layer can switch automatically when errors or latency exceed thresholds, as described in our guide to model routing for enterprise LLMs.
Multi-region and hybrid placement
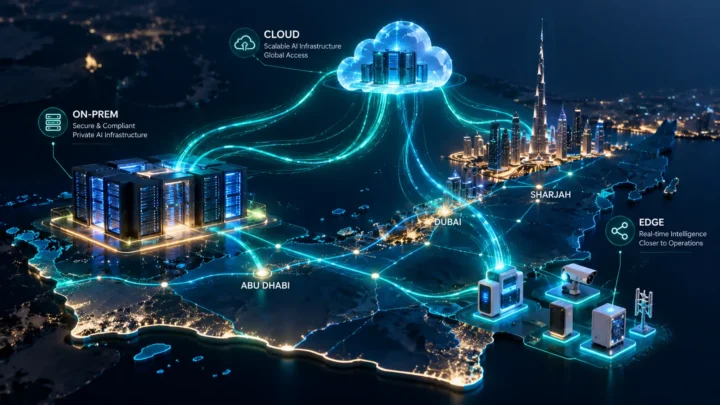
Spread critical serving and retrieval across regions, or across cloud and on-prem environments. Edge deployments can keep local operations running when connectivity is lost, as discussed in edge AI for enterprises.
Graceful degradation
Design reduced-function modes in advance: return cached answers, show search results instead of generated summaries, or route users to human agents. A clear, honest degraded experience is far better than a broken one.
Version pinning and change control
Pin model versions where providers allow it, test new versions against evaluation sets before switching, and track deprecation notices so changes are planned rather than forced on you.
Resilience for agentic AI
Agents add new risks because they act, not just answer. A failed tool call mid-workflow can leave records half updated, and an agent retrying aggressively can amplify an outage. Build in safeguards:
- Idempotent actions and clear transaction boundaries so steps can be retried safely.
- Timeouts, retry limits and circuit breakers on every tool and model call.
- Checkpoints that let a workflow resume rather than restart from the beginning.
- Escalation to a human when an agent cannot complete a task within policy.
Fallback models need particular care in agentic systems. A smaller substitute model may follow tool-calling formats differently or reason less reliably over long tasks, so it may be safer to pause high-impact actions during an incident and keep only read-only or low-risk steps running.
Building and testing an AI resilience plan
Resilience exists only if it is tested. A practical plan follows these steps:
- Classify use cases by business criticality, and define recovery time and acceptable degradation for each.
- Map dependencies, including models, providers, regions, vector stores, identity services and tools.
- Design fallbacks for each critical dependency, and document who can trigger them.
- Prepare prompts and evaluations for fallback models so their quality is known before an incident.
- Run game days that simulate provider outages, capacity shortages and model changes.
- Review after incidents and feed the lessons into architecture and contracts.
Measures to track
- Time to detect and time to recover for AI incidents, by use case.
- Fallback readiness: the share of critical use cases with a tested alternative.
- Quality of fallback models on current evaluation sets.
- Dependency concentration across providers, regions and shared services.
Contracts matter as much as code. Understand provider SLAs, deprecation policies and exit terms. Our guide to avoiding AI vendor lock-in shows how portability supports resilience.
Ownership and governance of AI resilience
Resilience planning often falls between teams: platform engineering owns infrastructure, product teams own features and risk teams own continuity. Make ownership explicit.
Include AI services in business continuity and operational resilience programmes, report on fallback readiness alongside other critical systems, and make sure questions from auditors or regulators about AI dependencies can be answered quickly. In regulated sectors, confirm specific continuity requirements with your compliance teams.
Resilience also has a cost, so match investment to criticality. A customer-facing service or a workflow that moves money may justify active redundancy across providers and regions. An internal drafting assistant may only need a clear outage message and a documented manual workaround. Making these trade-offs explicit, and agreeing them with business owners in advance, avoids both over-engineering and unpleasant surprises during an incident.
Finally, communicate. Users and support teams should know what a degraded mode looks like, how long it might last and where to turn, so that an AI incident is handled calmly rather than escalating into a wider loss of confidence.
Discuss AI resilience at Enterprise Private AI UAE 2027
Resilience gets a dedicated keynote in Dubai. On Day 2 (18 March 2027), the Resilience Keynote: AI Resilience: What Happens When Models, Clouds or APIs Fail? tackles the scenarios in this guide, building on the Day 1 CXO Panel: Cloud vs On-Prem vs Edge: The New Enterprise AI Operating Model. Join CTOs, CISOs and enterprise architects, with speakers from organisations including Microsoft, Capgemini, KPMG and Accenture. Check the full agenda, choose your pass or submit an abstract if you have resilience lessons to share.
Frequently asked questions
What is AI resilience?
AI resilience is an organisation's ability to keep AI-powered services working safely and predictably when a model, cloud region, API provider or supporting component fails or degrades. It combines redundancy, graceful degradation, monitoring and tested recovery plans.
What happens if an LLM API provider goes down?
Without a fallback, every feature that depends on that API stops working. Resilient designs route traffic to a tested alternative model, on another provider or on private infrastructure, or switch to a reduced-function mode such as cached answers or human handoff.
How do you test AI resilience?
Run game days that simulate provider outages, region failures, capacity shortages and model version changes, then measure how services behave and how quickly teams respond. Fallback models should have prepared prompts and evaluation results before any real incident.
Is AI resilience covered at Enterprise Private AI UAE 2027?
Yes. Day 2 of the summit in Dubai, 18 March 2027, features the Resilience Keynote: AI Resilience: What Happens When Models, Clouds or APIs Fail? The event brings together CTOs, CISOs and enterprise architects.