Model routing is the practice of automatically sending each LLM request to the most suitable model, based on the task’s complexity, cost, latency target and data sensitivity, instead of sending everything to one default model. In an enterprise, a routing layer lets you use small, inexpensive models for routine work, larger models for hard problems and private models for sensitive data, all behind one consistent interface.
As organisations adopt a portfolio of commercial, open-weight and fine-tuned models, routing becomes a strategic control point. This guide explains the main routing patterns, a reference architecture and how to roll routing out safely.
Why enterprises need model routing
A single-model strategy is simple but wasteful. The most capable model is rarely the most economical choice for classification, extraction or short summaries, and it may not be permitted to see certain data at all.
- Cost: routine requests can run on smaller models at a fraction of the compute.
- Latency: smaller or local models often respond faster for interactive use cases.
- Data control: sensitive prompts can be kept on private or in-country infrastructure.
- Resilience: if one model or provider fails, traffic can be redirected.
- Flexibility: new models can be introduced without rewriting applications.
The strategic benefit is often the last one. Model capabilities and prices change quickly, and an enterprise that has hard-coded one provider into dozens of applications cannot take advantage of better or cheaper options. A routing layer turns model choice into a configuration decision rather than a re-engineering project.
Common model routing patterns
There is no single routing algorithm. Most enterprise implementations combine several of the following patterns.
| Pattern | How it works | Best for |
|---|---|---|
| Rule-based | Routes by application, user group, task type or data classification | Clear policies and compliance boundaries |
| Classifier-based | A lightweight model predicts task complexity or category, then picks a model | Mixed workloads with varied difficulty |
| Cascade (escalation) | Tries a small model first and escalates if confidence or validation fails | Cost-sensitive tasks with verifiable outputs |
| Cost and latency aware | Chooses based on current price, load and response time budgets | High-volume, latency-critical services |
| Failover | Switches to an alternative model or region when the primary errors or slows | Business-critical applications |
Data-aware routing
For regulated enterprises, the most important rule is often about data rather than difficulty. A router can read classification labels or detect personal data and send those requests only to models hosted in approved environments. This is where routing meets security architecture, so see Zero Trust for LLMs for the wider control set.
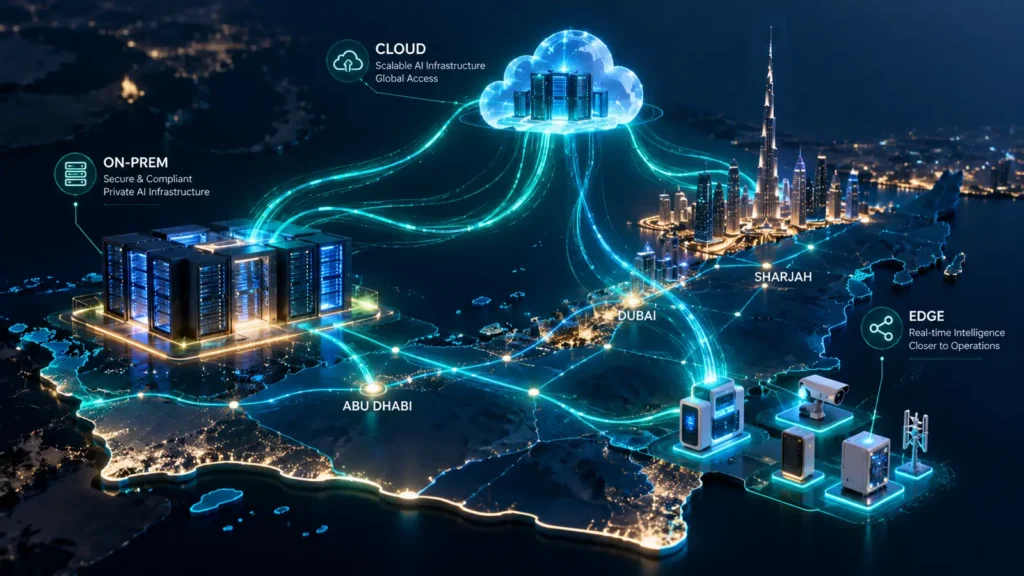
In the UAE, data-aware routing is a practical way to keep regulated workloads on in-country or private infrastructure while still allowing less sensitive tasks to use external models. The rules themselves should reflect your own legal and compliance guidance, and every routing decision should be logged so you can demonstrate where each request was processed.
A reference architecture for model routing
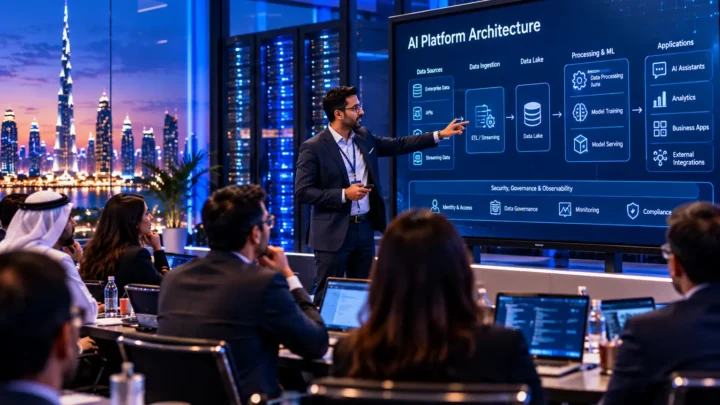
Routing is usually implemented in an AI gateway that sits between applications and models. A typical request flow looks like this:
- Ingress: the application calls one internal endpoint with its identity and request metadata.
- Policy check: the gateway applies authentication, quotas and data classification rules.
- Route decision: rules, a classifier or a cost model selects the target model.
- Execution: the request goes to an API model or a self-hosted endpoint running on engines such as vLLM or TensorRT-LLM.
- Validation: outputs are checked by guardrails or validators, and a cascade may escalate at this point.
- Telemetry: the gateway logs the model chosen, tokens, latency, cost and outcome.
Over time, this gateway often grows into a broader AI control plane that manages models, agents, policies and data access in one place.
Measuring whether model routing works
Routing decisions must be evaluated continuously, because models, prices and workloads all change. Track a balanced set of measures:
- Quality on representative evaluation sets for each route, not just overall.
- Escalation rate in cascades, and how often escalated answers differ meaningfully.
- Cost per request and per business task, compared with a single-model baseline.
- Latency percentiles, especially for interactive applications.
- Policy adherence, confirming that sensitive data never reached unapproved models.
All of this depends on strong telemetry, which is why routing and AI observability should be designed together rather than bolted on later.
Pitfalls to avoid
Routing adds a new decision layer to every request, so it needs the same discipline as any other production system. Watch for these traps:
- Over-engineering early: start with simple rules before investing in learned routers.
- Ignoring prompt compatibility: different models respond differently to the same prompt, so maintain and test model-specific templates.
- Hidden quality loss: savings mean little if users quietly lose trust, so monitor feedback and evaluation scores.
- Opaque decisions: log why each route was chosen so you can explain outcomes to auditors and product owners.
- Untested fallbacks: failover routes that are never exercised tend to fail when needed. Our article on AI resilience covers how to test them.
Rolling out model routing step by step
A phased rollout keeps risk low and builds evidence for each routing decision:
- Centralise access. Move applications onto a single gateway endpoint before changing any routing behaviour.
- Baseline. Record quality, cost and latency for current traffic on the existing default model.
- Add policy routes first. Enforce data classification rules, which deliver compliance value immediately.
- Introduce cost routes gradually. Shift one well-understood task type to a smaller model and compare results against the baseline.
- Add failover. Configure and test alternative models for business-critical applications.
- Review regularly. Revisit routes whenever a new model, price change or workload shift appears.
Shadow testing, where a candidate model processes copies of live requests without serving users, is a useful way to gather evidence before switching traffic.
See model routing in practice at Enterprise Private AI UAE 2027
Routing has its own hands-on session in Dubai. On Day 1 (17 March 2027), the Partner Deep-Dive Lab: Model Routing as Strategy: Choosing the Right Model for the Right Workload explores routing design in depth, following the Infrastructure Keynote: GPU Economics, Inference Routing & the Cost of Scaling AI earlier that afternoon. Join CTOs, heads of AI and platform engineering leaders, alongside speakers from organisations including Microsoft, Accenture, Capgemini and Infosys. Review the agenda and book your pass. Building routing technology yourself? Explore Deep-Dive Lab partnerships.
Frequently asked questions
What is model routing in LLMs?
Model routing is the automatic selection of which language model handles each request, based on factors such as task complexity, cost, latency and data sensitivity. It lets enterprises combine small, large, commercial and private models behind a single interface.
How does model routing reduce costs?
Routing sends routine tasks such as classification or short summaries to smaller, cheaper models and reserves large models for complex reasoning. Because a large share of enterprise requests are routine, this can lower average cost per request without hurting quality, provided each route is evaluated.
What is a cascade router?
A cascade router tries a smaller model first and escalates to a larger model only if the answer fails a confidence or validation check. It works best for tasks where outputs can be verified automatically.
Is there a session on model routing at Enterprise Private AI UAE 2027?
Yes. Day 1 of the Dubai summit, 17 March 2027, includes the Partner Deep-Dive Lab: Model Routing as Strategy: Choosing the Right Model for the Right Workload, alongside a keynote on GPU economics and inference routing.