AI vendor lock-in happens when switching away from a model provider, cloud platform or AI tool becomes so costly or disruptive that an enterprise effectively loses the choice. You avoid it by putting abstraction layers between applications and providers, keeping ownership of your data, prompts and evaluations, and designing critical AI workloads so they could run on an alternative model or environment.
Some dependency is unavoidable, and some is worth accepting for speed. The goal is not zero lock-in but deliberate lock-in: knowing where you depend on a vendor, what it would cost to leave, and having a credible exit plan.
Why AI vendor lock-in matters more than usual
Enterprises have managed lock-in with databases, ERP and cloud for decades. AI adds new pressures:
- A fast-moving market: model capability and pricing shift frequently, so today’s best choice may not be next year’s.
- Regulatory change: data residency or sector rules may require moving workloads to private or in-country infrastructure.
- Cost exposure: inference spend grows with usage, and a single supplier controls the price.
- Resilience: an outage or model deprecation at one provider can halt every dependent application.
- Behavioural coupling: prompts and agents are tuned to one model’s quirks, so migration is harder than swapping an API endpoint.
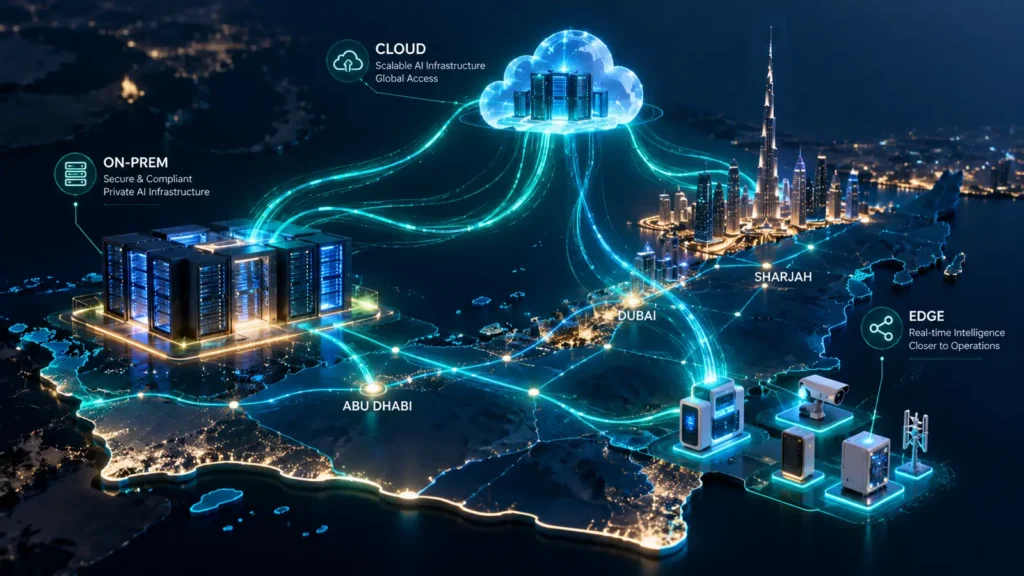
Sovereignty adds a further dimension for organisations in the UAE and the wider region. Leaders increasingly want to know not only which vendor they depend on, but where that vendor processes data and which jurisdiction governs it. A stack that can move between a global API, a sovereign cloud region and on-prem infrastructure gives far more room to respond to new requirements.
Where AI lock-in hides across the stack
Lock-in rarely comes from one big decision. It accumulates layer by layer.
| Layer | How lock-in happens | Mitigation |
|---|---|---|
| Models | Applications call one provider’s proprietary API and features directly | A gateway with a common interface; regular tests against alternative models |
| Prompts and agents | Prompts and tool definitions tuned to one model; agent frameworks tied to one platform | Store prompts as versioned assets; prefer open agent and tool interfaces |
| Fine-tuning | Custom models trained on a platform that will not export weights | Fine-tune open-weight models, or confirm export rights contractually |
| Data and embeddings | Vector stores tied to a proprietary format or embedding model | Keep source documents and re-embedding pipelines; record embedding model versions |
| Infrastructure | Workloads built on proprietary serving stacks | Containerised serving with open engines such as vLLM where practical |
| Observability | Logs and evaluation results held only in a vendor tool | Export telemetry to systems you control; own the evaluation datasets |
A useful exercise is to walk through this table for one production workload and estimate, honestly, how long a switch would take. The answer is often longer than leaders expect, and the slowest layer is rarely the model itself.
Architecture patterns that keep you portable
A handful of patterns do most of the work.
Put a gateway between apps and models
Route every model call through an internal gateway or AI control plane. Applications talk to a stable internal API, and the gateway handles provider specifics. Switching or adding a model becomes a configuration change rather than a rewrite. It also enables model routing, sending each workload to the model that best balances cost and quality.
Own your evaluation suite
The real barrier to switching is uncertainty about whether the new model is good enough. A maintained set of representative test cases, scored automatically, turns migration from a leap of faith into a measured decision.
Keep the data layer yours
Store source documents, metadata and chunking logic in systems you control, and treat embeddings as rebuildable. If you can regenerate your vector index with a different embedding model, you are not locked into the current one.
Mix open-weight and proprietary models
Running at least some workloads on open-weight models, in a private cloud or on-prem, keeps skills and infrastructure ready for a broader move if pricing, regulation or resilience requires it. Our sovereign AI stack guide covers what to own and what to rent.
Contract and commercial safeguards
Architecture handles technical portability. Contracts handle the rest. Discuss these points with procurement and legal:
- Clear rights over your data, prompts, outputs and any fine-tuned model artefacts.
- Data export in usable formats, within a defined period, at exit.
- Notice periods for model deprecation and material pricing changes.
- Data residency commitments aligned with UAE requirements, including Federal Decree-Law No. 45 of 2021 and, where relevant, DIFC or ADGM rules.
- Clarity on whether your data may be used to train the provider’s models.
Negotiate these terms at the start of a relationship, when you have the most leverage, rather than at renewal. This is not legal advice; confirm terms with your legal and compliance teams.
Balancing portability against speed
Abstraction has a cost. Every layer you add must be built and maintained, and a lowest-common-denominator interface can hide features that give a real advantage. A sensible approach is to tier workloads:
- Critical, long-lived workloads: invest in full portability, tested failover and a documented exit plan.
- Differentiating features: accept a provider-specific capability where it is worth it, but record the dependency and the exit cost.
- Experiments: move fast on any platform, on the understanding that anything reaching production moves behind the gateway.
Portability also underpins resilience. If a provider fails, the same abstraction that prevents lock-in lets you fail over, as covered in our guide to AI resilience. Review your dependency map at least annually, and whenever a major contract comes up for renewal, so that lock-in remains a choice rather than an accident.
Plan a portable AI stack at Enterprise Private AI UAE 2027
Enterprise Private AI UAE 2027 takes place in Dubai on 17–18 March 2027. On Day 1, the Architecture Deep Dive The Sovereign AI Stack: What Enterprises Should Own vs Rent tackles where to accept dependency and where to stay independent. On Day 2, the Resilience Keynote AI Resilience: What Happens When Models, Clouds or APIs Fail? examines the failover side of portability. Join CTOs, enterprise architects and platform leaders, with speakers from organisations including Microsoft, Accenture, Capgemini and Infosys. Explore the agenda, choose a pass, or see partner opportunities for technology providers.
Frequently asked questions
What is AI vendor lock-in?
AI vendor lock-in is a situation where moving away from a model provider, cloud or AI platform becomes so costly or disruptive that you effectively lose the choice. It builds up through proprietary APIs, data formats, tuned prompts and contracts.
How can enterprises avoid AI vendor lock-in?
Put a gateway between applications and model providers, keep ownership of data, prompts and evaluation sets, and design critical workloads so they can run on alternative models. Back this up with contract terms covering data export and deprecation notice.
Are open-weight models a solution to vendor lock-in?
Open-weight models reduce dependency because you can host them on infrastructure you choose. They are not a complete solution, as lock-in can still arise from serving platforms, data formats and tooling.
What contract terms reduce AI vendor lock-in?
Useful terms include clear rights over data, outputs and fine-tuned artefacts, data export at exit, notice of model deprecation and pricing changes, and residency commitments. Confirm all terms with your legal and procurement teams.