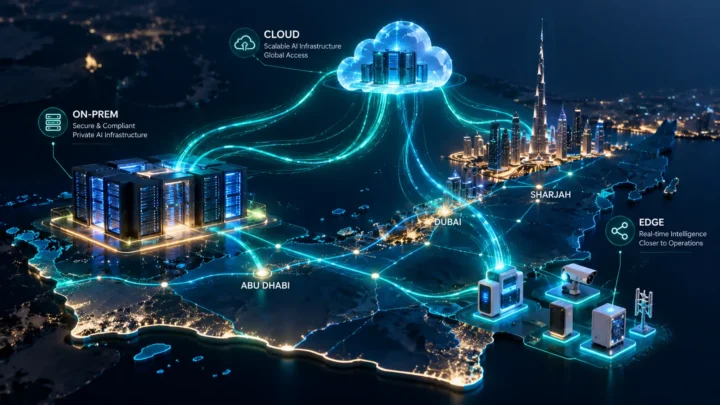
Private AI vs public cloud LLM is a choice between control and convenience: private AI runs models on infrastructure you govern, while public cloud LLMs are consumed as shared, provider-managed services. Most enterprises should not choose one for everything; they should decide per workload, based on data sensitivity, volume, latency and the skills they have in-house.
Below is a structured comparison and a decision framework you can take to your architecture board.
What each option actually means
Public cloud LLM
A public cloud LLM is a model accessed through a provider’s API or managed service. The provider runs the infrastructure, updates the model and scales capacity. You send prompts and receive completions, typically paying per token. Enterprise tiers usually add contractual commitments on data use, retention and regional processing, but the runtime remains outside your direct control.
Private AI
Private AI covers any deployment where the organisation controls where the model runs and who can access data in flight. That includes dedicated cloud tenancies, private cloud, on-premises GPU clusters and edge devices. Models are often open-weight and served with engines such as vLLM or TensorRT-LLM, though some providers also offer isolated or dedicated deployments of proprietary models.
The boundary between the two is blurring. Dedicated capacity in a public cloud, with customer-managed keys and in-country processing, can deliver much of the control of private AI with less operational effort, so evaluate the specific deployment rather than the label.
Private AI vs public cloud LLM: side-by-side comparison
| Factor | Public cloud LLM | Private AI |
|---|---|---|
| Data control | Governed by contract and provider settings | Governed directly by your own infrastructure and policies |
| Time to first value | Hours to days | Weeks to months, depending on platform maturity |
| Cost profile | Pay per token, low commitment | Capacity cost whether used or not, lower marginal cost at scale |
| Model access | Latest frontier models, changing on provider timelines | Chosen models and versions, stable until you change them |
| Latency | Depends on region and shared load | Predictable and can sit close to users or machines |
| Operational burden | Low, mostly integration and governance | High: serving, scaling, patching, monitoring and GPUs |
| Customisation | Limited to provider features | Full control over fine-tuning, quantisation and serving |
Neither column wins outright. The right answer depends on which rows matter most for a given use case, and that weighting changes from one department to the next.
When public cloud LLMs are the better choice
- Early experimentation, where speed of learning matters more than unit cost.
- Low-sensitivity workloads, such as drafting public content or summarising non-confidential material.
- Spiky or unpredictable demand that would leave dedicated GPUs idle for long periods.
- Tasks that need the most capable frontier reasoning, where private alternatives are not yet comparable on your evaluation set.
Public APIs also let small teams ship without building a serving platform. For many organisations, that is the fastest path to proving value before deciding where workloads should live in the long term.
When private AI is the better choice
- Workloads touching personal data, regulated records or material under contractual residency terms.
- High, steady inference volume where owned or reserved capacity becomes cheaper per request.
- Latency-sensitive applications close to users, machines or factory floors.
- Use cases that require fine-tuning, deep customisation or guaranteed model versions that will not change underneath you.
- Environments with strict audit needs, where you must show exactly where data was processed and by what.
In the UAE, where the federal PDPL sits alongside separate DIFC and ADGM regimes and sector requirements, private deployment often simplifies compliance conversations. It does not remove obligations, so confirm specifics with your legal and compliance teams. Our guide on whether private AI is compliant with UAE data law covers this in more depth.
Hidden risks on both sides of the decision
Comparison tables tend to flatter whichever option a team already prefers. Before committing, look explicitly at the risks that rarely appear in vendor material.
Risks of relying on public cloud LLMs
Providers can change pricing, rate limits, terms or model behaviour on their own timelines. A model update that improves average quality may still break a carefully tuned prompt in your workflow. Outages and regional capacity limits affect every customer at once, and switching providers is harder than it looks once prompts, tools and evaluation results are tied to one model family.
Risks of running private AI
Private AI moves operational risk in-house. GPU supply, capacity planning, patching, security hardening and on-call support become your responsibility. Teams can also fall behind the capability curve if they standardise on one open-weight model and stop re-evaluating alternatives. Underused clusters are a common and expensive failure mode.
Neither set of risks is a reason to avoid an option. They are reasons to design for portability, monitor quality continuously and keep a tested fallback for critical workloads.
A decision framework for hybrid estates
Most enterprises end up hybrid. The goal is to make hybrid deliberate rather than accidental. A five-question test per use case works well:
- Data: what is the highest classification of data the workload will see, including retrieved documents and logs?
- Volume: is demand steady enough to keep dedicated capacity busy?
- Latency: does the user or system need responses within tight, predictable limits?
- Capability: does the task genuinely need a frontier model, or would a smaller model perform well enough on your evaluation set?
- Exit: how hard would it be to move this workload if pricing, terms or regulation changed?
Combine the answers with a routing layer and a single policy engine, and you can send each request to the most appropriate model without rebuilding applications. Our guides to model routing for enterprise LLMs and avoiding AI vendor lock-in cover implementation patterns.
Revisit the scoring at least once a year. Model capability, pricing and regulation all move quickly, and a workload that belonged on a public API last year may now be a strong candidate for private hosting, or the reverse.
Debate the trade-offs at Enterprise Private AI UAE 2027
Where AI should run is the central question of Enterprise Private AI UAE 2027: Cloud, On-Prem & Edge Architecture, taking place in Dubai on 17–18 March 2027. On Day 1, the Keynote Enterprise Private AI in 2027: Where Should AI Actually Run? is followed by the CXO Panel Cloud vs On-Prem vs Edge: The New Enterprise AI Operating Model, giving a curated room of 150–200 technology leaders a direct look at how peers are splitting workloads. Expect speakers from organisations including Microsoft, Capgemini, Infosys and KPMG. Explore the agenda and secure your pass.
Frequently asked questions
What is the difference between private AI and a public cloud LLM?
Private AI runs models on infrastructure the organisation controls, such as dedicated cloud tenancy, private cloud, on-premises clusters or edge devices. A public cloud LLM is consumed through a provider's API, with the provider running the model and infrastructure.
Is private AI more secure than public cloud LLMs?
Private AI gives you more direct control over where data is processed and who can access it, but it is only as secure as your own operations. Public cloud enterprise tiers can be very secure too, so compare controls, contracts and audit evidence rather than labels.
Is private AI cheaper than using an LLM API?
It can be for high, steady workloads that keep dedicated capacity busy, especially with smaller models. For low or unpredictable volumes, public APIs are usually cheaper once staff and idle capacity are included.
Can an enterprise use both private AI and public cloud LLMs?
Yes, and most do. A routing layer and a shared policy engine can send each request to the right model based on data sensitivity, cost and capability.