AI infrastructure cost optimization is the practice of matching every AI workload to the cheapest infrastructure that still meets its latency, accuracy and data-control requirements, then measuring and tuning that match continuously. For most enterprises, the largest savings come from higher GPU utilisation, smarter model selection and disciplined capacity planning rather than from negotiating unit prices alone.
As LLM pilots turn into production services, infrastructure bills tend to grow faster than usage. This guide breaks down where AI infrastructure money actually goes, the levers that reduce it, and how to build a cost discipline that survives scale across cloud, on-prem and edge.
Where AI infrastructure spend really goes
Compute gets the headlines, but an enterprise AI platform has several cost layers. Understanding each one is the first step, because optimising the wrong layer delivers little.
| Cost layer | What drives it | Typical optimisation lever |
|---|---|---|
| GPU compute | Model size, request volume, utilisation, idle reserved capacity | Batching, quantisation, right-sizing, scheduling |
| Storage | Model weights, checkpoints, vector indexes, logs | Tiering, retention policies, deduplication |
| Networking | Cross-region traffic, egress, moving data to GPUs | Co-locating data and compute, caching |
| Software and licences | Platform tooling, managed services, support contracts | Consolidation, open-source serving where suitable |
| People and operations | Platform engineering, on-call, MLOps effort | Automation, shared platforms, standard templates |
Two layers are routinely underestimated: data movement and operational effort. Moving large datasets or embeddings between regions or clouds can quietly rival compute costs, and a fragmented estate of one-off deployments multiplies the engineering hours needed to keep it running.
The core levers of AI infrastructure cost optimization
Most savings come from a small number of technical levers applied consistently. They compound: a right-sized model served efficiently on well-utilised hardware is far cheaper than any single tweak in isolation.
Raise GPU utilisation
Idle or underused accelerators are the most common source of waste. Continuous batching, request queuing and sharing GPUs across several smaller models can lift utilisation substantially. Serving engines such as vLLM and TensorRT-LLM were built largely to solve this problem, using techniques such as paged attention and in-flight batching.
Right-size the model
Not every task needs a frontier-scale model. Classification, extraction and routine summarisation often run well on smaller or distilled models, which need less memory and fewer GPUs. Quantisation, which runs weights at lower numerical precision, can reduce the memory footprint further, but test quality on your own data before rolling it out.
Route workloads deliberately
A routing layer that sends simple requests to small models and complex ones to larger models is one of the highest-leverage controls available. We cover the design patterns in our guide to model routing for enterprise LLMs.
Cache and reuse
Prompt caching, semantic caching of frequent answers and reuse of shared context all reduce the number of tokens you pay to process. Retrieval pipelines can also be tuned to send fewer, more relevant chunks to the model.
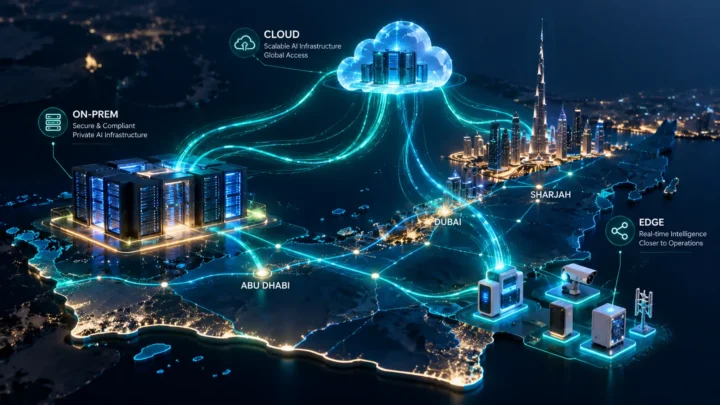
Choosing the right placement: cloud, on-prem or edge
Placement is a cost decision as much as an architecture decision. Each environment has a different cost shape, and the cheapest option depends on how steady and predictable your workloads are.
- Public cloud suits spiky, experimental or fast-changing workloads, where paying for elasticity is worth more than owning hardware.
- On-prem or private cloud can become more economical for steady, high-volume inference, provided you can keep the hardware busy and staff the operations.
- Edge reduces network transfer and latency for local workloads at sites, branches or devices, but adds fleet management overhead.
- Hybrid combinations let you run baseline load on owned capacity and burst to cloud for peaks.
In the UAE, placement is also shaped by data residency and sector rules, which can narrow the options before any cost comparison begins. Our overview of private AI deployment in the UAE explains the regulatory context, and you should confirm specific obligations with your legal and compliance teams.
Building a FinOps discipline for AI
Technical levers only stick when there is a cost discipline around them. Traditional cloud FinOps practices still apply, but AI introduces new units of measurement and new owners.
- Define unit economics. Track cost per request, per thousand tokens or per business outcome, not just total monthly spend.
- Tag and attribute. Label every model endpoint, GPU pool and pipeline by team, product and environment so costs can be charged back or shown back.
- Set budgets and alerts. Give each use case a budget and alert on anomalies, such as a prompt change that sharply raises average token counts.
- Review capacity regularly. Compare reserved or owned capacity against actual demand and adjust commitments on a fixed cadence.
- Make trade-offs visible. Present cost alongside latency and quality so product owners choose consciously rather than defaulting to the largest model.
None of this works without good telemetry. Token counts, latency, cache hit rates and GPU metrics need to flow into one view, which is why cost work and AI observability are best planned together.
Common mistakes that inflate AI infrastructure costs
Many enterprises repeat the same avoidable errors as they scale. Watch for these patterns:
- Buying or reserving GPU capacity before workloads and utilisation targets are understood.
- Using one large model for every use case because it was the first one approved.
- Letting prompts and retrieved context grow unchecked, which silently raises token consumption.
- Keeping every log, embedding and checkpoint forever, with no retention policy.
- Running separate, duplicated stacks for each business unit instead of a shared platform.
- Optimising cost in isolation and degrading quality or latency until users abandon the service.
The fix is rarely a single project. It is a habit of measuring, reviewing and adjusting, owned jointly by platform engineering, finance and the business teams consuming AI. For a deeper look at the per-request side of the equation, see our breakdown of LLM inference cost and GPU spend.
Explore AI infrastructure economics at Enterprise Private AI UAE 2027
Cost is a recurring thread on Day 1 (17 March 2027) of Enterprise Private AI UAE 2027 in Dubai. The Infrastructure Keynote: GPU Economics, Inference Routing & the Cost of Scaling AI examines how utilisation and routing shape spend, and the Closing Keynote: The Economics of Private AI: Cost, Control and Competitive Advantage connects infrastructure choices to board-level returns. Expect speakers from organisations including Microsoft, Accenture, KPMG and Infosys, plus CXO roundtables where peers compare what has actually worked. Review the full agenda and secure your place on the pricing page, where early-bird rates are available for a limited time.
Frequently asked questions
What is AI infrastructure cost optimization?
AI infrastructure cost optimization is the continuous practice of running each AI workload on the most economical infrastructure that still meets its performance, quality and compliance needs. It covers compute, storage, networking, software and operational effort, not just GPU prices.
What is the biggest source of wasted AI infrastructure spend?
Underused GPU capacity is usually the largest source of waste. Reserved or owned accelerators that sit idle, or serve one small model each, cost the same as busy ones, so batching, sharing and right-sizing typically deliver the fastest savings.
Is on-prem AI infrastructure cheaper than cloud?
It can be for steady, high-volume workloads that keep hardware well utilised, but not for spiky or experimental ones. The answer depends on utilisation, staffing, data residency requirements and how long you expect to run the workload.
Where can I learn more about AI infrastructure economics in Dubai?
Enterprise Private AI UAE 2027, held in Dubai on 17 and 18 March 2027, covers GPU economics, inference routing and the cost of scaling AI on Day 1. The summit brings together CTOs, CIOs and heads of AI for keynotes, panels and deep-dive labs.