LLM inference cost is the line item that surprises most enterprise AI programmes. Training and fine-tuning get the headlines, but once an assistant, copilot or agent is in production, every user and every request consumes GPU time. Costs grow with adoption, longer prompts and more capable models, often faster than the value they create.
This guide explains what drives inference cost, nine practical levers to cut GPU spend without hurting quality, and how to compare cloud, on-prem and edge on economics rather than instinct.
What drives LLM inference cost?
- Tokens in and out. Long prompts, large retrieved contexts and verbose answers all consume compute. Output tokens are generated one by one and are usually the slower, more expensive part.
- Model size. Larger models need more GPU memory and compute per token.
- Context length. Very long contexts increase memory use and slow every request.
- Latency targets. Strict response-time goals limit how aggressively requests can be batched.
- Utilisation. An idle GPU still costs money. Low utilisation is the hidden multiplier on every private deployment.
The metric that matters: cost per task
Cost per GPU hour or per million tokens is useful for engineers, but leadership needs cost per completed task: per resolved support ticket, per processed contract, per generated report. Pair it with quality and latency, and every optimisation can be judged on whether it improves the business outcome, not just the infrastructure bill.
Nine levers to cut LLM inference cost
1. Right-size the model
Many enterprise tasks, such as classification, extraction, routing and short summaries, do not need the largest model available. Smaller open-weight models are cheaper to run and far easier to host privately.
2. Route requests to the cheapest capable model
A model router sends simple requests to a small model and escalates only complex ones to a larger model. Cascades like this often deliver most of the quality at a fraction of the cost.
3. Quantise
Running a model at 8-bit precision roughly halves its memory footprint compared with 16-bit, and 4-bit roughly quarters it. That allows larger batches or smaller GPUs, with a quality impact you should test on your own evaluation set.
4. Use continuous batching and an efficient serving engine
Modern serving engines such as vLLM and NVIDIA TensorRT-LLM batch requests continuously and manage GPU memory efficiently, increasing the number of requests each GPU can serve.
5. Cache aggressively
Cache shared prompt prefixes such as system prompts and policies, and cache complete answers for repeated questions. Prompt and response caching cut both cost and latency.
6. Trim the context
Retrieve fewer, better passages instead of stuffing the context window. Better chunking and re-ranking in RAG pipelines often improve answer quality and reduce tokens at the same time.
7. Control output length
Set sensible maximum output lengths and ask for structured, concise answers. Fewer output tokens means faster and cheaper responses.
8. Speculative decoding
A small draft model proposes tokens that the larger model verifies in parallel, increasing generation speed for the same hardware.
9. Place workloads where they are cheapest to run well
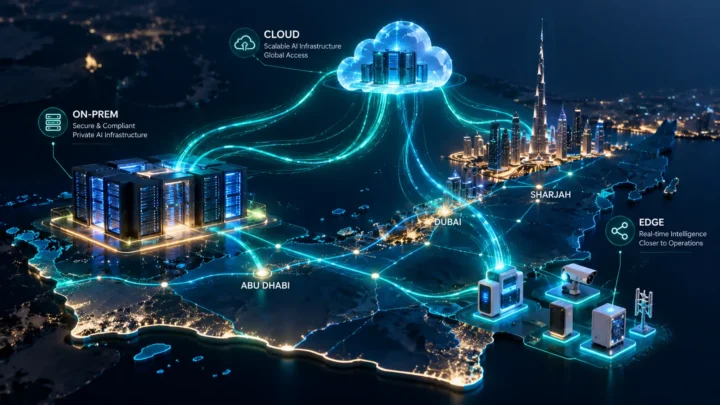
Steady, predictable workloads are candidates for reserved or dedicated capacity; spiky and experimental workloads fit pay-as-you-go cloud; latency-critical or disconnected sites may justify edge inference.
Cloud vs on-prem vs edge: the economics
| Placement | Cost model | Wins when | Watch out for |
|---|---|---|---|
| Public API | Per token | Low or unpredictable volume; fastest start | Costs scale linearly with usage; data leaves your boundary |
| Cloud GPUs (sovereign or private) | Per GPU hour, reserved discounts | Growing workloads that need elasticity | Paying for idle reserved capacity |
| On-prem | Upfront capital, low marginal cost | High, steady utilisation; strict data control | Hardware lead times, power, cooling and skills |
| Edge | Device and fleet costs | Low latency, offline sites, data that must stay local | Smaller models only; fleet management overhead |
Placement is also a data-control decision. Our guide to private AI in the UAE explains how residency and governance shape where each workload should run, and the Zero Trust for LLMs blueprint covers per-identity quotas that stop runaway consumption.
A simple plan to get inference cost under control
- Route all model traffic through a gateway that records tokens, latency and cost by application and team.
- Build an evaluation set for your top use cases so you can test cheaper models and settings safely.
- Introduce routing and caching first: they usually deliver the fastest savings.
- Review utilisation monthly before buying or reserving more GPUs.
- Report cost per task, quality and adoption together to leadership.
GPU economics on the agenda in Dubai
GPU economics, inference routing and the cost of scaling AI is a dedicated infrastructure keynote at Enterprise Private AI UAE 2027, followed by a pilot-to-production case session on building a hybrid private AI stack. Join enterprise AI, cloud and infrastructure leaders in Dubai on 17–18 March 2027. See the programme or choose your pass.
Frequently asked questions
What is LLM inference cost?
LLM inference cost is the total cost of generating responses from a large language model in production: GPU or API charges, plus the supporting infrastructure, networking, storage and operations needed to serve every request at the required speed.
How can enterprises reduce LLM inference cost?
The most effective levers are using smaller models where they are good enough, routing each request to the cheapest capable model, caching repeated prompts and answers, trimming context, quantising models, batching requests efficiently and placing steady workloads on well-utilised dedicated capacity.
Is on-prem LLM inference cheaper than cloud?
It can be for steady, high-volume workloads where GPUs stay busy, because the hardware cost is spread across many requests. For spiky or experimental workloads, cloud or API pricing is usually cheaper. Utilisation is the deciding factor.
What metric should I use to track LLM cost?
Track cost per completed task (for example, per resolved ticket or per processed document) alongside quality and latency. It connects infrastructure spend directly to business value.