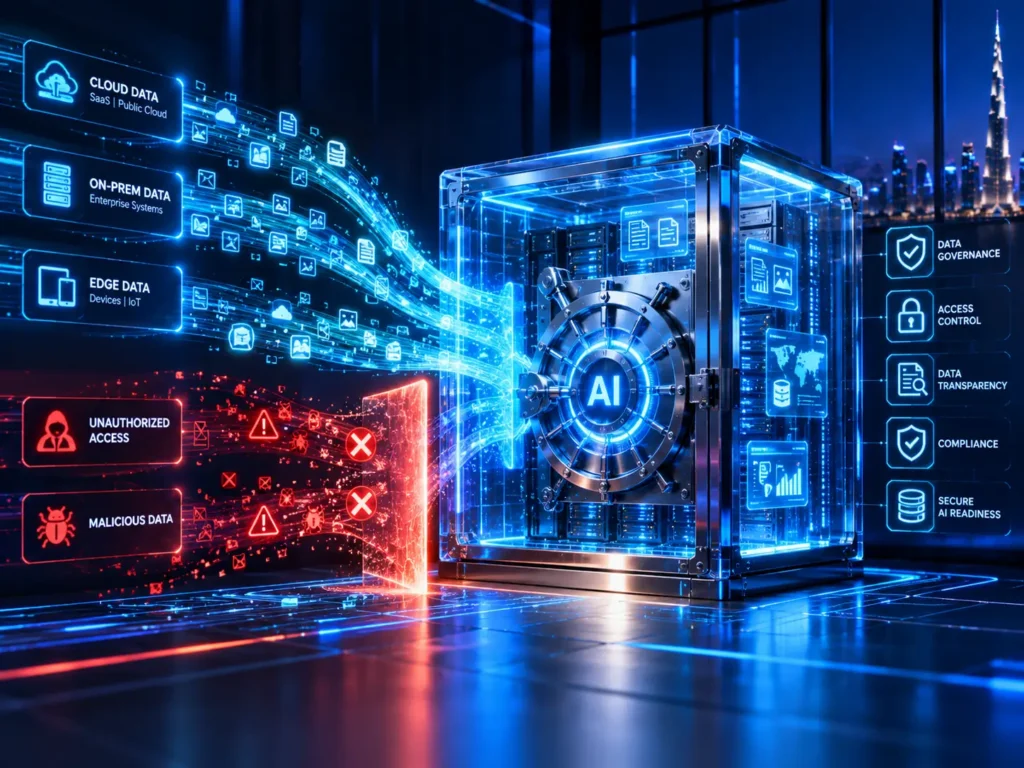
LLM data leakage is the unintended exposure of sensitive information through a large language model system, and in most enterprises the biggest risk sits not in the model itself but in the prompts, logs, caches, embeddings and fine-tuning data that surround it. Closing those gaps requires treating every AI data store as a sensitive system in its own right.
Security reviews often focus on whether a model might reveal its training data. That risk is real, but the more common problems are mundane: a tracing tool storing full prompts, a vector database readable by everyone, or a support transcript copied into a fine-tuning set. This guide maps the leak channels and the controls that address them.
Where LLM data leakage actually happens
The OWASP Top 10 for LLM Applications 2025 treats sensitive information disclosure and vector and embedding weaknesses as distinct risk categories, which reflects how many places data can escape. The table below maps the main channels.
| Channel | How leakage happens | Primary control |
|---|---|---|
| Prompts to external APIs | Sensitive data leaves your boundary and may be retained under provider terms | Data classification rules, gateway redaction, contractual review |
| Application and gateway logs | Full prompts and completions stored with broad access and long retention | Redaction, access control, short retention |
| Observability and tracing tools | Third-party tools capture entire conversations by default | Configured capture levels, self-hosting or masking |
| Vector databases | Embeddings and source chunks readable without document permissions | Permission-aware retrieval, tenant isolation, encryption |
| Response and semantic caches | One user’s answer served to another with a similar question | User- or permission-scoped cache keys |
| Fine-tuning and evaluation data | Personal or confidential data memorised by a model | Data minimisation, de-identification, dataset review |
| Model outputs and agent actions | Model reveals restricted content or sends it to an external destination | Output filtering, outbound allow-lists, least privilege |
Notice that only the last row depends on model behaviour. Every other channel is ordinary data engineering, which means familiar disciplines such as classification, access control and retention can close most of the gap.
Logs and traces: the overlooked data store
Logging is essential for debugging, cost tracking and incident response, which is exactly why it becomes a leak channel. Teams switch on full prompt capture during a pilot and never switch it off, so production logs end up holding customer details, contract terms and internal discussions, often readable by far more people than the source systems.
Practical controls for logs include:
- Redacting or tokenising personal and confidential fields before they are written.
- Separating operational metrics, such as latency, tokens and errors, from content logs, so most users never need content access.
- Restricting content logs to a small, named group with access reviews.
- Setting short retention periods and enforcing deletion automatically.
- Checking the default capture settings of every observability and tracing tool you connect.
Good AI observability and good data protection are compatible, but only if content capture is a deliberate design choice.
Embeddings are not anonymisation
A common misconception is that converting text into vectors makes it safe. It does not. Research has shown that embeddings can sometimes be inverted to recover approximations of the original text, and most vector databases store the source chunks alongside the vectors anyway.
The bigger day-to-day risk is retrieval without permissions. If a RAG pipeline indexes an entire document repository using a service account, any user can ask a question that surfaces passages from files they could never open directly. Indirect prompt injection makes this worse, because a malicious instruction can deliberately pull sensitive content into an answer; see our guide on how to prevent prompt injection across the enterprise.
Controls for vector stores
- Inherit the classification of the source data and protect the store accordingly.
- Filter retrieval results by the requesting user’s existing permissions, ideally at query time.
- Isolate tenants and business units with separate indexes or enforced metadata filters.
- Propagate deletions, so removing a source document also removes its chunks and vectors.
Fine-tuning, memory and caches
Three further channels deserve attention as AI programmes mature.
Fine-tuning data. Models can memorise parts of their training data, especially rare or repeated strings. Minimise personal data in training sets, de-identify where possible, and review datasets before use. Once a model has learned something, removing it is far harder than deleting a record.
Agent memory. Agents that remember previous conversations create a long-lived store of user context. Scope memory to the individual user, make it visible and deletable, and keep it out of shared contexts.
Caches. Response and semantic caches save cost, but a cache keyed only on the question can serve one user’s answer, including their data, to someone else. Include user or permission context in cache keys for anything sensitive. Our guide to LLM inference cost covers caching as a cost lever.
Where workloads are too sensitive for any of these copies to sit on shared infrastructure, processing them inside trusted execution environments adds a further layer of protection. Our guide to confidential AI explains how data stays protected while models are running, and where that protection stops.
A practical checklist to prevent LLM data leakage
- Inventory every place prompts, outputs, embeddings and training data are stored.
- Classify each store at the level of the most sensitive data it can hold.
- Route model traffic through a gateway that can redact and enforce data rules.
- Make retrieval permission-aware and remove all-seeing service accounts.
- Set retention and deletion rules for logs, caches, vectors and memory.
- Restrict outbound destinations so models and agents cannot send data externally.
- Test regularly with red-team prompts designed to extract restricted content.
In the UAE, these controls also support obligations under Federal Decree-Law No. 45 of 2021 and the DIFC and ADGM data protection regimes. Confirm specific requirements with your legal and compliance teams.
Take control of AI data at Enterprise Private AI UAE 2027
Data control is a core theme of Day 2 at Enterprise Private AI UAE 2027, held in Dubai on 17–18 March 2027. The Architecture Deep Dive Data Control Beyond the Model (Day 2, 10:45) focuses on exactly the stores and flows covered here, while the Technical Keynote Securing LLMs Across Hybrid Enterprise Environments (Day 2, 10:00) sets the wider security context.
Join a curated room of 150–200 technology and security leaders, with speakers from organisations including Accenture, Capgemini and Infosys. Explore the agenda or book your delegate pass.
Frequently asked questions
What is LLM data leakage?
LLM data leakage is the unintended exposure of sensitive information through a large language model system. It can happen through model outputs, but in enterprises it more often happens through prompts sent to third parties, logs, caches, vector databases and fine-tuning data.
Can embeddings leak sensitive data?
Yes. Research has shown that embeddings can sometimes be inverted to recover approximations of the original text, and vector search can surface sensitive passages to the wrong user. Vector stores should be protected with the same classification and access controls as the source documents.
How do I stop sensitive data appearing in LLM logs?
Redact or tokenise sensitive fields before logging, separate full prompt logs from operational metrics, restrict who can read them and set short retention periods. Review observability and tracing tools too, because they often capture full prompts by default.
Where can I discuss LLM data control with peers in Dubai?
Enterprise Private AI UAE 2027 in Dubai on 17–18 March 2027 includes the Day 2 Architecture Deep Dive Data Control Beyond the Model, plus sessions on securing LLMs and confidential AI.