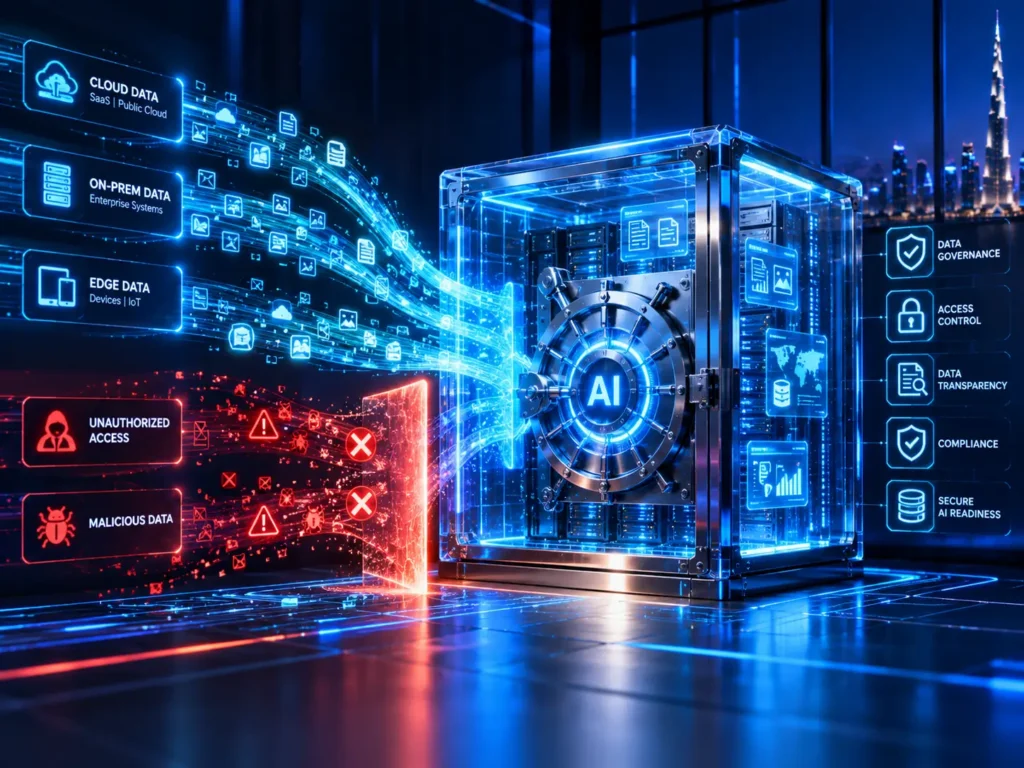
For an enterprise LLM, data residency means that every copy of your data the system creates or touches stays in a location you have approved, which in the UAE often means in-country. That includes prompts, retrieved documents, embeddings, logs and fine-tuning sets, not just the database you started with. Sovereign AI goes a step further: it asks who controls the stack, not only where it sits.
What does data residency mean for an enterprise LLM?
Data residency is the physical or geographic location where data is stored and processed. In a traditional application that is a short list of databases and backups. In an LLM deployment the list is longer, because the model pipeline copies, transforms and caches data at almost every step.
Two related terms are worth separating early. Data sovereignty is the idea that data is subject to the laws of the jurisdiction where it is held, and that the owner can enforce control over it. Sovereign AI applies that idea to the whole AI stack: infrastructure, models, data and operations.
A deployment can meet residency and still fall short on sovereignty. If a foreign provider administers your in-country GPUs remotely, or ships telemetry abroad, the servers are local but control is not.
Where does LLM data actually live?
Most residency gaps appear in places teams did not think to look. Map each of these surfaces before you pick a platform:
- Prompts and responses: often contain personal, commercial or regulated content, and may be retained for abuse monitoring or debugging.
- Retrieval sources and vector stores: a vector store holds embeddings, numerical representations of text used for semantic search. Embeddings can reveal information about the source text, so treat them as the same class as the documents.
- Logs, traces and caches: application logs, prompt caches and observability tools frequently store full conversation content. Our article on LLM data leakage in logs, caches and embeddings covers this in detail.
- Fine-tuning and evaluation data: training sets, feedback labels and test cases often include real records.
- Model weights and adapters: weights fine-tuned on sensitive data may themselves need to be protected and kept in approved locations.
- Telemetry and support access: vendor diagnostics, crash dumps and engineer remote access can move data across borders without any application-level change.
Residency, sovereignty and control: how do they differ?
Leaders often use these terms interchangeably in procurement. They answer different questions, and each needs its own evidence.
| Concept | Question it answers | Typical evidence or control |
|---|---|---|
| Data residency | Where is data stored and processed? | In-country regions, network egress rules, data flow diagrams |
| Data sovereignty | Whose laws apply, and who can compel access? | Provider ownership and jurisdiction review, contractual terms, legal advice |
| Operational control | Who can administer, update and observe the system? | Customer-held encryption keys, access approvals, local operations staff |
| Model control | Who decides which model version runs and what it is trained on? | Version pinning, open-weight or licensed models, change management |
Treat the table as a ladder. Residency is the first rung and the easiest to verify. The higher rungs cost more and take longer, so apply them where the data justifies it.
How do UAE rules shape LLM deployments?
The UAE has a federal personal data protection law, and the DIFC and ADGM free zones operate their own data protection regimes. Regulators for sectors such as financial services and healthcare may add expectations on top, including how data is stored, transferred and outsourced. Government and critical-infrastructure entities often work to stricter internal or national requirements.
The practical point is that obligations differ by data class, sector and entity, and they change. We do not recommend designing from a single rule of thumb such as “everything must stay in the UAE” or “nothing needs to”. Our guide on whether private AI is compliant with UAE data law goes further, and your legal and compliance teams should confirm the specifics for your organisation.
Other GCC markets have their own approaches, so a regional rollout needs a per-country view rather than one UAE-shaped design.
Which architecture patterns keep data in-country?
There is no single right answer. The pattern should follow the data class and the workload. For a wider comparison of placement options, see cloud vs on-prem vs edge for enterprise LLMs.
1. In-country public cloud region
You use a hyperscaler region located in the UAE with managed model services or GPU instances. This is the quickest route and often meets residency requirements for data at rest. Check whether the model service, its logs, abuse-monitoring stores and support access also stay in-region, because managed services sometimes route some processing elsewhere.
2. Sovereign or private cloud with a local operator
A UAE-based provider or a dedicated private cloud hosts your models. This improves operational and jurisdictional control and suits sensitive workloads. The trade-off is capacity planning, a narrower model catalogue and more responsibility for your own platform engineering.
3. On-premises or edge inference
You run open-weight or licensed models in your own data centres or at the site where data is produced. Control is highest, but so are the costs of hardware, power, cooling and skills. It fits the most restricted data and low-latency sites, as discussed in our piece on what enterprises should own versus rent in a sovereign AI stack.
4. Hybrid with policy-based routing
A gateway classifies each request and sends it to the right place: restricted data to local models, low-risk tasks to larger external models. Most enterprises end up here, because a single location rarely suits every workload. It depends on reliable classification and logging at the gateway, which becomes a critical control point.
These placement trade-offs are central to the technical discussion at Enterprise Private AI UAE 2027 in Dubai, where practitioners compare how they have made these choices in production.
A five-step framework for residency decisions
- Inventory the data surfaces. For each LLM use case, list every place data is created, copied or sent, using the surfaces above. Include vendors and sub-processors.
- Classify by sensitivity and obligation. Group data into a few classes, for example public, internal, confidential and regulated. Ask legal and compliance to state the residency requirement for each class.
- Set a minimum control level per class. Decide whether a class needs in-country storage only, in-country processing, customer-held keys or full local operation.
- Match workloads to patterns. Use the patterns above. Where one use case spans several classes, split the pipeline rather than raising the whole system to the strictest level.
- Enforce and evidence it. Apply network egress controls, region-locked deployments, key management and audit logging. Re-test whenever a vendor, model or feature changes.
What mistakes weaken residency in practice?
- Checking only the model endpoint. The primary region is local, but caches, logs and monitoring tools are not.
- Ignoring embeddings and indexes. Teams protect source documents but let vector data sit in a global SaaS service.
- Accepting vendor claims without evidence. Ask for data flow documentation, sub-processor lists and contract terms covering support access and telemetry.
- Treating residency as a one-time review. New features, model upgrades and fallback routes can change where data goes. Plan failover carefully: a fallback to an overseas endpoint during an outage can quietly break your residency position.
- Over-restricting everything. Putting low-risk workloads on scarce local capacity raises cost and slows delivery without reducing meaningful risk.
Next steps for technology and security leaders
Start with a short, concrete exercise rather than a policy rewrite. Pick your three most valuable LLM use cases, draw the data flow for each, and mark every point where data leaves your approved boundary. Take that output to legal, compliance and your security team, and agree the residency requirement for each data class in writing.
Then choose the simplest pattern that satisfies those requirements, and add routing only where a single location does not work. Keep the evidence, such as flow diagrams, region configurations and contract clauses, in a form an auditor can read.
If you want to compare notes with peers who are making these decisions, the Enterprise Private AI UAE 2027 summit takes place in Dubai on 17–18 March 2027 and focuses on running LLMs across cloud, on-premises and edge without losing control of data.
Frequently asked questions
What is the difference between data residency and sovereign AI?
Data residency is about where data is stored and processed. Sovereign AI is broader: it also covers who controls the infrastructure, models and operations, and which jurisdiction can compel access. A deployment can satisfy residency while still lacking sovereignty.
Do all enterprise LLM workloads in the UAE need to stay in-country?
Not necessarily. Requirements depend on the data class, the sector, the entity and applicable law. Classify your data and ask legal and compliance teams to confirm which workloads must stay in-country and which can use external services.
Do embeddings and logs count as data for residency purposes?
Yes, treat them as the same class as the source data. Embeddings can reveal information about the text they represent, and logs or caches often hold full prompts and responses. Include them in your data flow map.
Is an in-country cloud region enough for sovereign AI?
Often it is enough for residency of data at rest, but not always for sovereignty. You still need to check where managed model services process data, who has administrative and support access, and who holds the encryption keys.
Can a hybrid architecture meet UAE data residency needs?
Yes, if it is designed for it. A gateway can route restricted data to local models and low-risk requests to external ones. It needs reliable classification, region-locked fallbacks and audit logging to be trusted.