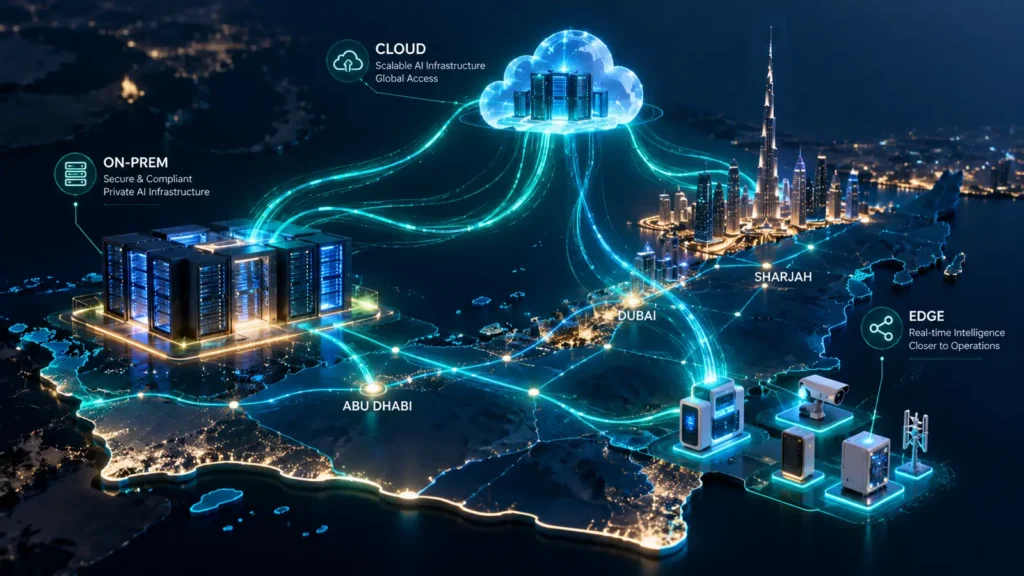
Enterprise LLMs should run wherever a workload’s data sensitivity, latency requirement and usage pattern point, and for most organisations that means more than one place. Cloud suits variable demand and quick access to strong models, on-premises infrastructure suits sensitive data and steady high-volume use, and edge suits tasks that need a local response or must work offline. The practical answer is a hybrid, decided workload by workload rather than by a blanket policy.
What do cloud, on-prem and edge mean for LLMs?
The terms are used loosely, so it helps to fix them. Inference means running a trained model to produce an answer, and it is where most enterprise LLM spend and risk sit once pilots end.
- Cloud: inference runs in a provider’s environment, either through a shared managed API or on dedicated capacity in your own cloud tenancy, ideally in a region you choose.
- On-prem: inference runs on GPUs (graphics processors used to run models) in a data centre or colocation facility where you control the hardware, network and access.
- Edge: inference runs close to where data is created, such as a branch, factory, vehicle or device, normally with smaller models.
Each option trades control, speed of access, cost shape and operational burden differently.
| Factor | Cloud | On-prem | Edge |
|---|---|---|---|
| Data control | Depends on tenancy, region and contract terms | Highest, as data stays inside your boundary | High, as data can stay at source |
| Access to frontier models | Strongest and fastest | Limited to models you can license or host | Limited to compact models |
| Cost shape | Variable, pay for use | Largely fixed, rewards high utilisation | Spread across many devices or sites |
| Latency | Network-dependent | Predictable inside your network | Lowest, works without a round trip |
| Operational burden | Lowest | Highest | High at scale, across many locations |
| Typical fit | Spiky demand, experimentation, general productivity | Regulated data, steady core workloads | Field operations, real-time, offline use |
Which factors should decide where an LLM runs?
Five questions do most of the work. Answer them for each workload, not for the organisation as a whole.
- Data sensitivity and residency. What data enters the prompt, and where must it legally and contractually stay?
- Latency and connectivity. Does the user or machine need a response in a fraction of a second, or must the system work when the network is poor?
- Utilisation and cost shape. Is demand steady enough to keep owned GPUs busy, or spiky enough that paying per use is cheaper?
- Model capability. Does the task need a frontier model, or will a smaller, tuned model do the job well enough?
- Operational capacity. Do you have the platform, security and MLOps skills to run inference reliably, around the clock?
The last question is the one most often skipped. Owning infrastructure without the people to run it simply moves the risk inside the building.
When does each option win?
Cloud: variable demand and fast access to capability
Cloud is the sensible default for new use cases, uncertain demand and tasks that benefit from the most capable models. It removes procurement lead times and lets teams test value before committing capital. The risks to manage are data handling, retention terms, regional availability and dependence on a single provider.
On-prem: sensitive data and predictable load
On-premises hosting wins when prompts contain highly sensitive or regulated data, or when a core workload runs at high, steady volume. Owned capacity can become cheaper per request once utilisation is consistently high, a trade-off examined in our guide to self-hosted LLM versus API cost. The price is capital outlay, hardware lead times, and responsibility for patching, scaling and failure recovery.
Edge: proximity, speed and independence
Edge wins when a round trip to a data centre is too slow, too costly in bandwidth, or impossible. Examples include inspection on a production line, assistance for field engineers, or on-site document handling where connectivity is unreliable. Edge models are usually smaller and narrower, so they need clear scope and a route to escalate harder requests. Our article on which workloads belong at the edge goes deeper on selection.
How do you decide? A four-step placement framework
Use this sequence to turn the factors above into a defensible decision.
- Classify workloads. List each LLM use case with its data classes, users, latency needs and expected volume. Group them into a few tiers, for example public or low-risk, internal, and restricted.
- Set the non-negotiables. For each tier, record hard constraints: residency, isolation, audit, uptime and approved models. These rule options out before cost is considered.
- Test the economics on what remains. Compare realistic utilisation against cloud pricing and owned capacity, including staff, power, networking and idle hardware. Treat vendor figures as inputs to test, not conclusions.
- Choose a default and name the exceptions. Assign each tier a default location, then document when a workload may move. Review placement regularly, because models, prices and demand change.
If the choice is mainly between hosted and self-managed environments, our comparison of private AI and public cloud LLMs covers that decision in more detail.
What does a hybrid architecture look like in practice?
A workable hybrid has one front door. Applications call a gateway, and the gateway applies policy to decide where each request goes. This is model routing: sending every request to the most suitable model and location based on sensitivity, cost and quality needs.
A common pattern
- Restricted requests are routed to on-prem or dedicated in-country capacity.
- General requests go to cloud models, with burst capacity for peaks.
- Edge devices handle local tasks with small models and escalate to a larger model when confidence is low or the task exceeds their scope.
What must stay consistent everywhere
Placement flexibility only works if the controls travel with the workload. Identity and access, prompt and output logging, policy enforcement, cost tracking and evaluation should look the same in every location. Otherwise each environment becomes its own governance gap, and logs, caches and embeddings quietly accumulate sensitive data in places nobody is watching.
Plan for failure as well. A hybrid design should let traffic fall back to another location when a provider, region or model is unavailable, with the quality and data-handling trade-offs agreed in advance.
What does this mean for UAE and GCC enterprises?
For organisations in the UAE and wider GCC, residency and sector rules often shape placement before economics do. Banks, government entities, healthcare providers and energy companies commonly face requirements about where data is stored and processed, and who can access it. Requirements differ by sector, emirate and contract, so confirm the specifics with legal and compliance teams rather than assuming a location is acceptable.
Sovereign and in-country cloud options, local colocation and on-prem builds all give leaders more ways to keep regulated workloads inside national boundaries while still using cloud for lower-risk work. These placement trade-offs are a core theme of the Enterprise Private AI UAE 2027 summit in Dubai on 17–18 March 2027, where technical leaders compare cloud, on-prem and edge architectures.
Which placement mistakes should you avoid?
- Choosing one location for everything. A single policy overprotects low-risk tasks or underprotects sensitive ones.
- Buying GPUs before measuring demand. Idle owned capacity is usually the most expensive option.
- Treating edge as a smaller cloud. Fleets of devices need update, monitoring and rollback processes that data-centre teams may not have.
- Ignoring exit costs. Build on open interfaces so a workload can move when economics or rules change.
- Forgetting secondary data. Logs, caches and vector stores need the same residency and retention discipline as prompts.
Next steps for your placement decision
Start small and make the reasoning visible. Within the next month, most teams can complete the following.
- Inventory current and planned LLM use cases, with data classes and volumes.
- Agree three or four workload tiers and the hard constraints for each.
- Run a cost comparison on the two or three highest-volume workloads using measured usage.
- Stand up a gateway with shared identity, logging and monitoring before adding locations.
- Test a fallback path between at least two environments.
If you want to pressure-test your approach against peers facing the same decisions, the Dubai summit on 17–18 March 2027 includes sessions on running LLMs across cloud, on-prem and edge. Bring your tiering and cost assumptions, and compare them with what others are finding in production.
Frequently asked questions
Should enterprise LLMs run in the cloud or on-premises?
It depends on the workload. Cloud suits variable demand and access to the most capable models, while on-premises suits sensitive data and steady high-volume inference. Most enterprises use both, assigning each workload to a location by data sensitivity, latency and utilisation.
When does edge AI make sense for LLMs?
Edge makes sense when a round trip to a data centre is too slow, too costly or unavailable. Typical cases are real-time operations, field work and sites with poor connectivity. Edge models are usually smaller, so they need a clear scope and a way to escalate harder requests.
Is on-prem LLM hosting cheaper than cloud APIs?
Only when utilisation is consistently high. Owned hardware carries fixed costs for capital, power, staff and idle time, so low or spiky demand usually favours pay-per-use cloud. Test the comparison with measured usage rather than vendor estimates.
What is a hybrid LLM architecture?
A hybrid LLM architecture runs models across more than one environment, such as cloud, on-prem and edge, behind a common gateway. The gateway routes each request by policy, while identity, logging and monitoring stay consistent in every location.
How does UAE data residency affect where LLMs run?
It can restrict where regulated or sensitive data may be stored and processed, which often points to in-country cloud or on-prem hosting for those workloads. Requirements vary by sector and contract, so confirm them with legal and compliance teams before fixing a design.