Use prompting to control how a model behaves, retrieval-augmented generation (RAG) to give it current and permissioned company knowledge, and fine-tuning to change its default style, format or specialist skill. For most enterprise use cases the right order is prompting first, RAG second and fine-tuning last, because each step adds cost, governance burden and operational complexity.
The three approaches are often presented as rivals. In practice they solve different problems, and the mistakes leaders make usually come from using one to do the job of another. This article sets out what each does, where each fails, and a simple decision framework you can apply to your own workloads.
What problem does each approach actually solve?
Start with definitions, because the terms are used loosely.
- Prompting means giving the model instructions, examples and context in the request itself. The model is unchanged; you are steering it.
- Retrieval-augmented generation (RAG) means searching your own documents or data at query time and placing the relevant passages into the prompt. The model answers using that material.
- Fine-tuning means continuing the model’s training on your own examples so that its weights, the numerical parameters that encode what it has learned, shift. Parameter-efficient methods such as LoRA (low-rank adaptation) train a small add-on instead of the whole model, which lowers cost.
A useful shorthand: prompting shapes behaviour, RAG supplies knowledge, and fine-tuning changes habits. If the model does not know something, fine-tuning is rarely the right fix. If it knows the facts but writes in the wrong register or format every time, it often is.
When is prompting enough?
Prompting is enough more often than teams expect, particularly with a capable base model. It suits tasks where the model already has the necessary general knowledge and you need to specify the role, tone, structure and constraints.
Good candidates include summarising meeting notes into a standard template, classifying support tickets against a fixed taxonomy, and drafting first-pass internal communications. Few-shot prompting, where you include a handful of worked examples, can close much of the remaining gap.
Prompting reaches its limits in three situations: the instructions become too long to maintain, the model needs facts it was never trained on, or the output must be identical in structure across very large volumes. Treat those as signals to consider the next option, not as failures.
When should you use RAG for enterprise data?
RAG is the default answer when an assistant must respond using internal policies, contracts, product documentation, tickets or knowledge bases. The model stays general; your data stays in your own systems and is fetched when needed.
Why RAG suits enterprise governance
RAG has four properties that matter to senior leaders:
- Freshness. Updating knowledge means re-indexing a document, not retraining a model.
- Permissions. Retrieval can filter by the user’s access rights, so a person only receives answers drawn from documents they could open themselves.
- Traceability. Answers can cite the source passages, which helps review, audit and user trust.
- Deletion. Removing a document from the index removes it from future answers, which is far harder with trained weights.
RAG is not free of risk. The vector database (the store of numerical representations, or embeddings, used for similarity search) becomes a sensitive asset in its own right. Our guide to RAG security and protecting vector databases and embeddings covers the controls in detail.
Where RAG disappoints
RAG quality depends on retrieval quality. Poorly chunked documents, stale indexes, inconsistent metadata and missing permissions data produce confident but wrong answers. Most failed RAG pilots are data-preparation problems, not model problems.
RAG also does not teach the model a new skill. If you need it to reason in a specialist notation or follow a rigid house style, adding more retrieved text will not reliably achieve that.
When does fine-tuning earn its place?
Fine-tuning is justified when you have a stable, well-defined behaviour gap that prompting cannot close reliably or economically. Typical cases include:
- Consistent structured output, such as a precise report format or domain-specific code or query syntax.
- Specialist vocabulary or tone, including terminology in Arabic and English that a general model handles unevenly.
- Running a smaller, cheaper model at the quality of a larger one for a narrow, high-volume task, which can reduce latency and inference cost.
- Shortening very long prompts by moving standing instructions into the model itself.
It also carries real obligations. You need a curated, representative training set, a held-out evaluation set, and a plan to repeat the process when the base model changes. Fine-tuned models need versioning, rollback and monitoring like any other production artefact.
The governance catch
Training data influences the weights, and a model can reproduce fragments of what it was trained on. Weights have no concept of which user is asking, so you cannot apply document-level permissions to knowledge held inside them. Do not fine-tune on content that different staff groups are entitled to see differently, and be cautious with personal or confidential records.
Your choice of base model also affects how freely you can do this. Open-weight models can be fine-tuned and hosted entirely within your environment, while proprietary models offer varying fine-tuning terms. See open-weight versus proprietary models for private LLM deployment for the trade-offs.
Fine-tuning vs RAG vs prompting: how do they compare?
| Criterion | Prompting | RAG | Fine-tuning |
|---|---|---|---|
| Best for | Behaviour, tone, simple structure | Current, internal, permissioned knowledge | Consistent style, format or specialist skill |
| Handles changing information | Poorly, unless pasted in manually | Well, through re-indexing | Poorly, requires retraining |
| Per-user access control | Not applicable | Possible at retrieval time | Not possible inside weights |
| Source citations | No | Yes, by design | No |
| Upfront effort | Low | Medium: data pipeline and index | High: dataset, training, evaluation |
| Ongoing effort | Prompt maintenance | Index quality and security | Retraining and model versioning |
| Main risk | Inconsistent output at scale | Bad retrieval, exposed embeddings | Data memorisation, stale model |
A five-question framework for choosing
Work through these questions for each use case, in order, and stop when you have a sufficient answer.
- Does the model need information it was not trained on? If yes, you need RAG or another way of supplying context. Fine-tuning is not a reliable way to add facts.
- Does that information change, or differ by user? If yes, RAG with permission-aware retrieval is close to mandatory.
- Is the remaining problem about how the model responds rather than what it knows? Try better instructions and examples first.
- Does a measured behaviour gap persist at your required volume? Only then consider fine-tuning, ideally with a smaller model for a narrow task.
- Can you evaluate and govern the result? If you have no evaluation set, no owner and no rollback plan, neither RAG tuning nor fine-tuning is ready.
The fifth question is the one most often skipped. Build the evaluation set before choosing a technique: a few hundred representative questions with agreed good answers is a sensible aim, reviewed by the people who know the domain. It turns an opinion contest into a comparison.
How do data residency and private deployment change the choice?
For UAE and wider GCC enterprises in regulated sectors, the approach you choose affects where data travels and where it rests. RAG keeps source documents in your own repositories and sends only selected passages to the model at query time. If the model runs in a private or in-country environment, that can simplify residency conversations, though you should confirm specifics with legal and compliance teams.
Fine-tuning moves data into a training pipeline, which has its own storage, access and retention implications. Training datasets, checkpoints and the resulting model are all assets that need classification and protection. Prompts and retrieved passages also end up in logs and caches, so treat those as data stores too; and once a system is live, AI observability lets you see which approach is actually delivering quality and at what cost.
Common mistakes to avoid
- Fine-tuning to add knowledge. The model may sound more informed without being accurate, and updating it is slow.
- Skipping prompting work. A weak prompt is the cheapest problem to fix and often the real cause.
- Treating RAG as only a model feature. It is a data engineering and access-control project.
- Using one approach everywhere. Different workloads in the same organisation justify different patterns.
- No re-evaluation. A new base model, a new document set or a changed policy can shift results without any code change.
Combining the three in practice
Mature systems usually blend them. A common pattern is a carefully prompted general model, with permission-aware RAG for knowledge, and a small fine-tuned model handling a narrow, high-volume step such as classification or structured extraction. Each layer has a clear purpose, an owner and a test.
Next steps for your team
Pick two or three live or planned use cases and run them through the five questions above. For each, write down the knowledge source, who is allowed to see it, how often it changes and what a good answer looks like. Build the evaluation set, test a prompted baseline, then add retrieval, and only then decide whether a measured gap justifies fine-tuning.
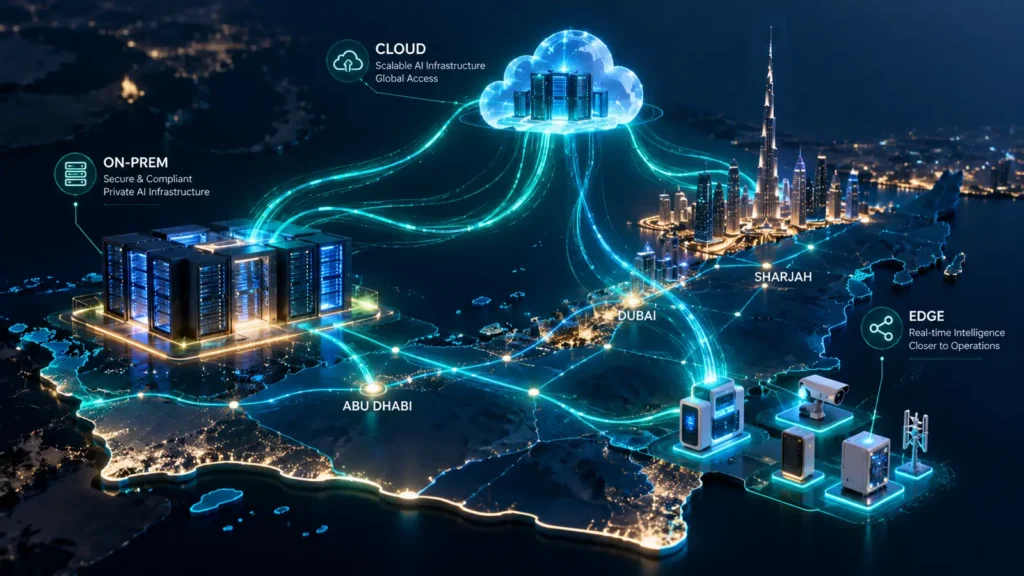
If you want to compare approaches with peers who run these systems in regulated environments, the technical sessions at Enterprise Private AI UAE 2027 in Dubai on 17–18 March 2027 cover cloud, on-prem and edge architecture; the summit programme and agenda sets out the topics.
Frequently asked questions
Is RAG better than fine-tuning for enterprise data?
For adding company knowledge, usually yes. RAG keeps information current, supports per-user permissions and can cite sources, none of which fine-tuning offers. Fine-tuning is better for consistent style, format or a narrow specialist skill.
Can you combine fine-tuning and RAG?
Yes, and many production systems do. A fine-tuned model can handle output format or domain language while RAG supplies current, permissioned facts at query time. Test the combination against an evaluation set to confirm each layer adds value.
Should we start with prompting before RAG or fine-tuning?
Yes. Prompting is the cheapest and fastest to change, and it gives you a baseline to measure against. Move to RAG when the model lacks knowledge, and to fine-tuning only when a measured behaviour gap remains.
Does fine-tuning on internal data create security risks?
It can. Trained weights may reproduce fragments of the training data, and they cannot enforce who is allowed to see what. Avoid fine-tuning on content with differing access rights, and classify datasets, checkpoints and models as sensitive assets.
What do you need before choosing an approach?
You need a clear use case, a source of truth for the data, an owner, and an evaluation set of representative questions with agreed answers. Without these, you cannot tell whether any approach is working.