An internal LLM platform is a shared, governed set of services that lets every business team use language models, enterprise data and tools through one consistent route, instead of each team building its own stack. Platform engineering is the discipline that makes it work: treat the platform as a product, give developers self-service paths, and build security, cost and observability controls into the platform itself. Done well, it turns scattered pilots into repeatable delivery.
Why do enterprises need an internal LLM platform?
Without a platform, the same pattern appears in most large organisations. One team signs up to a model API, another deploys an open-weight model on a spare GPU server, and a third builds a retrieval pipeline with its own vector database. Each works in isolation, and none shares identity, logging, cost tracking or data controls.
That fragmentation is expensive and risky. Security teams cannot see which data reaches which model. Finance cannot attribute spend. Engineers rebuild the same connectors and guardrails repeatedly. It is one of the reasons programmes stall, a theme explored in our piece on why enterprise AI programmes stall between pilot and production.
A platform replaces this duplication with a small number of well-run services. Product teams focus on the use case, while the platform team owns everything that is common and sensitive.
What layers does an internal LLM platform include?
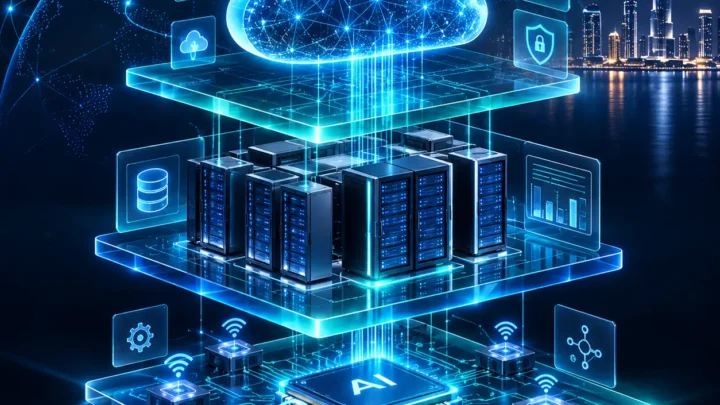
Think of the platform as six layers. Not every enterprise needs all of them on day one, but each should have a named owner and a decision about how it will be provided.
| Layer | What it does | Key platform decision |
|---|---|---|
| Access and gateway | Single entry point for model requests, with authentication, quotas and policy checks | One gateway for all models, internal and external |
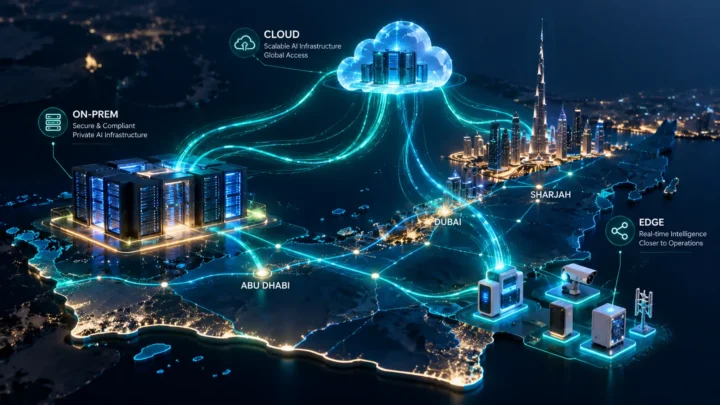
| Model serving | Runs hosted and self-managed models across cloud, on-premises and edge | Which models are approved, and where each may run |
| Data and retrieval | Connectors, indexing, embeddings and vector storage for retrieval-augmented generation (RAG) | How source-system permissions carry through to retrieval |
| Orchestration and tools | Prompt management, workflows, agent frameworks and tool integrations | Which frameworks are supported, and how tool access is granted |
| Observability and evaluation | Tracing, quality tests, cost attribution and incident signals | What is logged, for how long, and who can read it |
| Governance and security | Identity, policy enforcement, audit and data classification | Which controls are mandatory and enforced in code |
The gateway is the most useful first component
A model gateway is a service that sits between applications and models, exposing one consistent interface. It lets you swap models without rewriting applications, apply policy in one place and record usage per team. It is also where inference routing can later direct each request to the right model for cost, latency and data sensitivity.
Retrieval needs permission awareness
RAG means fetching relevant company documents at query time and giving them to the model as context. The platform should make sure the retrieval layer respects the same access rules as the source systems. Otherwise an assistant can surface a document that the person asking was never allowed to read. For guidance on choosing between retrieval, tuning and prompting, see our comparison of fine-tuning, RAG and prompting.
How should a platform team be organised?
The most common failure is staffing the platform like a project: a burst of build work, then a handover to an operations team that never owned the design. A better model is a standing platform team with a product owner, engineers who have run production systems, and a security partner embedded from the start.
Work from golden paths
A golden path is a pre-approved, well-documented way to achieve a common task, such as deploying a retrieval-based assistant or calling a model for summarisation. If the golden path is faster than going around it, teams adopt it voluntarily. Mandating a platform that is slower than a credit card and an API key rarely works.
Define what the platform team owns
- The platform owns: gateway, model serving, shared retrieval services, logging standards, evaluation tooling, cost reporting and baseline security controls.
- Product teams own: the use case, prompts, domain data quality, user experience and the business outcome.
- Shared with security and risk: data classification rules, approved model lists and incident response.
Clear boundaries prevent the platform team becoming a bottleneck for every request. They also settle the broader question of accountability, which we cover in who owns enterprise AI.
Should you build, buy or assemble the platform?
Few enterprises build every layer from scratch, and few can buy a single product that covers all six. The practical choice is usually to assemble: pick open or managed components for each layer, and own the integration and policy layer that ties them together.
| Approach | Strengths | Trade-offs | Best suited to |
|---|---|---|---|
| Build in-house | Full control, tailored to internal systems | High engineering cost, slow to mature, hard to hire for | Organisations with strong platform teams and unusual requirements |
| Buy a managed suite | Fast start, vendor support | Lock-in risk, limited customisation, data location constraints | Teams with small platform capacity and lower sensitivity workloads |
| Assemble from components | Flexibility, ability to replace layers | Integration effort, needs clear ownership | Most large enterprises with mixed cloud and on-premises estates |
Whichever route you take, keep the interfaces portable. A platform that hides model and cloud choices behind stable internal APIs is far easier to adapt than one wired directly to a single provider. Our guidance on avoiding AI vendor lock-in covers the practical tactics.
How do you embed security and governance without slowing teams down?
Policy documents do not stop a misconfigured application. Controls need to run in the request path, where the platform can enforce them every time. This is the idea behind moving from policy to runtime control.
A sensible baseline for the platform includes:
- Identity on every call. Users, services and agents authenticate, and requests carry that identity through to logs and data access.
- Data classification at the gateway. Restricted data is routed only to models approved for it, including models that run on-premises or in a sovereign region.
- Least-privilege tool access. Agents receive only the tools and permissions their task requires.
- Controlled logging. Prompts and responses often contain sensitive content, so retention and access to logs need the same care as the source data.
- Evaluation before release. Applications pass quality and safety tests before reaching users, and again when models change.
These controls align with a zero trust architecture for LLMs and AI agents, in which nothing is trusted because of where it runs. For UAE and wider GCC enterprises, the same gateway is a natural place to enforce residency rules. Which workloads must stay in-country is a question for your legal and compliance teams, and the platform should make their answer enforceable rather than advisory.
How do you manage cost and capacity?
Shared infrastructure invites shared overspending unless usage is visible. Give every team a budget, attribute every request to a team and use case, and report cost per outcome rather than only total spend.
On capacity, the key decision is which workloads justify dedicated accelerators and which can use pay-per-use services. Steady, high-volume, sensitive workloads often favour owned or reserved capacity, while spiky or experimental ones suit consumption pricing. The trade-offs are set out in our analysis of GPU economics for on-premises and cloud LLMs.
Plan for failure as well. Models are updated, APIs change and regions have outages. A gateway with fallback routes and a tested rollback process protects applications from all three.
A phased rollout that works
Resist the temptation to design the full platform before anyone uses it. A phased approach delivers value earlier and teaches you what teams actually need.
- Pick two or three use cases. Choose ones with a clear owner, accessible data and measurable value, and with different technical shapes, such as document search and drafting.
- Stand up the thin platform. Deliver the gateway, identity, basic logging and one approved serving option.
- Add shared retrieval and evaluation. Build these once the first applications show what is common.
- Publish golden paths and documentation. Make onboarding a matter of days, and measure it.
- Extend to agents, edge and additional regions. Add these when governance and observability are ready to cover them.
Measure the platform like a product: time to first deployment, share of AI applications using the golden path, cost visibility coverage and incident rates. Tie these to business results using the approach in our guide to enterprise AI ROI metrics for the board.
Next steps for platform and technology leaders
Start with an inventory. List every model, API key, vector store and AI application already running in your organisation, including those outside IT. That inventory defines the scope of your first platform release and exposes the highest risks.
Then appoint a platform product owner, agree what the platform team owns versus product teams, and decide which controls are mandatory from the first release. Choose the gateway first, because every later decision depends on it.
If you want to compare approaches with peers who are building the same thing, the architecture sessions at Enterprise Private AI UAE 2027 in Dubai on 17–18 March 2027 cover cloud, on-premises and edge platform design. You can review the summit programme and agenda to see which sessions match your platform roadmap.
Frequently asked questions
What is an internal LLM platform?
An internal LLM platform is a shared set of governed services that gives teams self-service access to models, enterprise data and tools. It centralises identity, logging, cost tracking and security so that product teams do not rebuild them for each application.
Who should own the internal LLM platform?
A dedicated platform engineering team with a named product owner should own it, working closely with security, data and risk teams. Product teams own their use cases, while the platform team owns shared services such as the gateway, serving and baseline controls.
Should we build or buy an enterprise LLM platform?
Most enterprises assemble the platform from open and managed components rather than building or buying everything. Own the integration, policy and gateway layers, and keep interfaces portable so models and providers can be replaced later.
What should we build first when creating an LLM platform?
Build the model gateway first, with authentication, basic logging and policy checks. It gives you one control point for access, cost attribution and later routing, and every other layer can be added around it.
How does an internal LLM platform support data residency?
The gateway can classify requests and route restricted data only to models approved for it, such as on-premises or in-country deployments. Confirm the exact residency requirements with your legal and compliance teams, then encode them as enforceable policy.