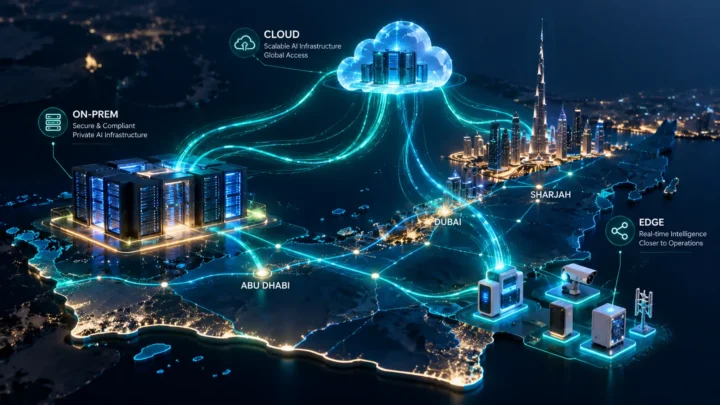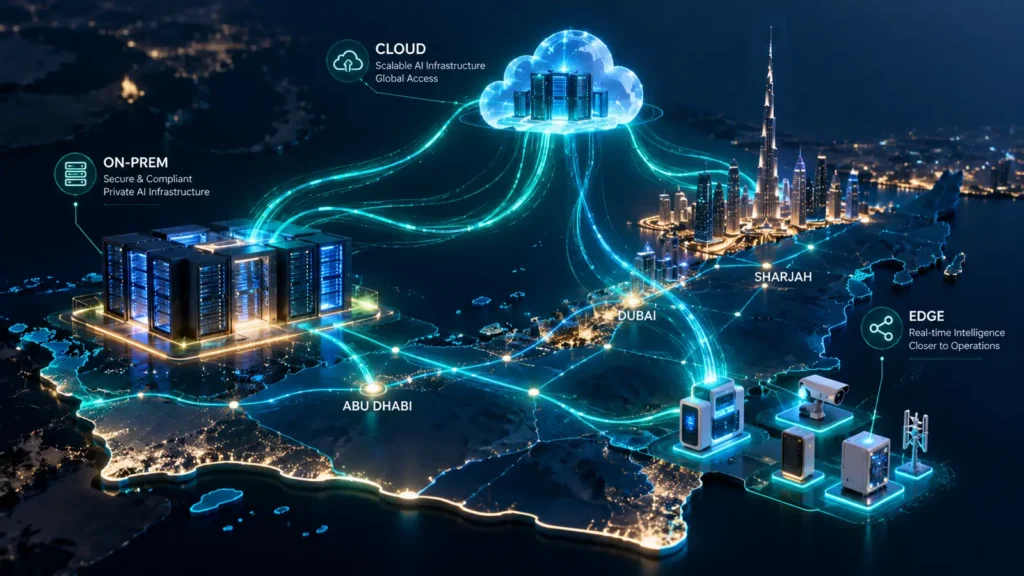
A hybrid AI architecture for banks splits large language model (LLM) workloads across public cloud, private cloud or on-premises infrastructure, and edge locations, according to data sensitivity, latency, cost and regulatory exposure. In the GCC, this usually means keeping customer-identifiable data and core banking context under the bank’s direct control, while using elastic cloud capacity for lower-risk work. The architecture succeeds or fails on the shared controls that sit across those venues, not on the venues themselves.
Why do GCC banks need a hybrid approach to AI?
No single venue suits every banking workload. Public cloud offers fast access to frontier models and elastic capacity, but some data cannot leave the bank’s boundary. On-premises infrastructure offers control and predictable behaviour, but it is slower to scale and expensive to keep current.
Three pressures push GCC institutions towards a mixed model:
- Data residency and sovereignty. Regulators across the Gulf have expectations about where customer and transaction data is stored and processed. These differ by country and sector, so legal and compliance teams must confirm what applies to each use case.
- Outsourcing and concentration risk. Relying on one external model provider for critical processes creates a dependency that supervisors and boards will question.
- Economics. Steady, high-volume inference tends to favour owned capacity, while spiky or experimental work favours pay-as-you-go cloud. Our analysis of where enterprise LLMs should run across cloud, on-prem and edge covers the trade-offs in more depth.
Which banking AI workloads belong where?
Start from the data, not the technology. Classify what each workload reads, writes and retains, then place it accordingly. The table below is a starting point for discussion, not a rule; your own risk appetite and regulator guidance will change it.
| Workload | Typical data sensitivity | Suggested venue | Main reason |
|---|---|---|---|
| Customer service assistant using account context | High | On-premises or in-country private cloud | Personal and financial data in prompts and retrieval |
| Credit and underwriting analysis support | High | On-premises or private cloud | Model risk, explainability and audit needs |
| Fraud and AML triage summarisation | High | On-premises or private cloud | Sensitive investigation data, low tolerance for leakage |
| Internal policy and procedure search | Medium | Private cloud, or approved cloud with controls | Proprietary content, moderate exposure |
| Marketing copy and research drafts | Low | Public cloud with data filtering | Elastic demand, limited sensitive input |
| Branch, ATM or kiosk interaction | Medium to high | Edge with small models, escalating to core | Latency and connectivity constraints |
What does a reference architecture look like?
Think in five layers. Each layer is the same regardless of where the models run, which is what keeps a hybrid estate manageable.
- Data layer. Classified sources, with retrieval indexes held in the same trust zone as the data they were built from.
- Model layer. A mix of hosted frontier models, open-weight models run in-house, and small specialised models at the edge.
- Routing layer. A policy-aware gateway that decides which model and venue handles each request, based on data class, task and cost.
- Control layer. Identity, access, prompt and output filtering, logging, and approval workflows applied uniformly.
- Observability and assurance layer. Monitoring of quality, drift, cost and incidents, feeding model risk management and internal audit.
The routing layer is where hybrid becomes practical. A request carrying customer account details is sent to an in-boundary model, while a request to summarise a public regulatory publication can go to the cheapest suitable cloud model. The same gateway can fall back to another venue when a provider is unavailable.
How do banks keep data control across venues?
Keep retrieval inside the trust boundary
Retrieval-augmented generation (RAG) feeds an LLM with documents fetched at query time. The vector database and embeddings behind it can reveal sensitive information, so they should be classified and secured like the source data. Do not send raw customer records to an external model simply because the retrieval step happened locally.
Treat logs and caches as data stores
Prompts, responses, traces and caches often hold the very data you are trying to protect. Set retention, masking and access rules for them from the start, and check what each cloud provider retains by default.
Apply zero trust to models and agents
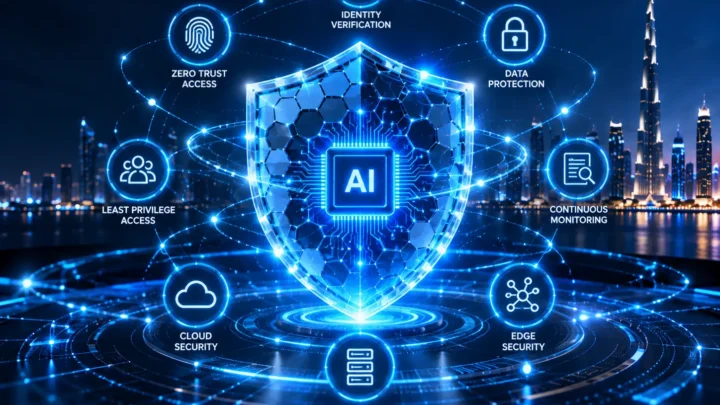
Every model call, tool call and agent action should be authenticated, authorised and logged, with no implicit trust based on network location. Our guide to a zero trust architecture for enterprise LLMs and AI agents sets out the pattern.
Understand what residency means for LLMs
Residency applies not only to stored data but to inference, logging, fine-tuning and support access. A model hosted in-country but administered or logged elsewhere may not meet your obligations. Read our explanation of what data residency means for LLMs in the UAE, then confirm requirements for each jurisdiction in which you operate.
How should governance and model risk be handled?
Banks already have model risk management disciplines. Generative AI should fit within them, not sit beside them. That means documented intended use, validation before release, ongoing monitoring, and clear ownership for each deployed model or agent.
Several adjustments are specific to LLMs:
- Validate behaviour on the bank’s own tasks, since general benchmarks say little about your credit memos or complaint letters.
- Keep a human reviewer in any decision that affects a customer’s access to credit, accounts or services.
- Version prompts, retrieval sources and model settings, so any output can be reproduced during an audit or complaint investigation.
- Test for prompt injection and data exfiltration before agents are given access to internal tools.
Regulators in the region continue to develop their expectations on AI, so build for traceability and explainability now rather than wait for final rules.
What goes wrong in hybrid deployments?
Most failures are organisational rather than technical. Watch for these patterns:
- Shadow venues. Business units adopt cloud AI tools outside the architecture because the sanctioned path is slow. Make the governed route the easiest one.
- Inconsistent controls. Policy is strict on-premises and loose in the cloud, or the reverse. Uniform policy enforcement at the gateway avoids this.
- Cost surprises. GPU capacity bought for peak demand sits idle, or cloud token spend grows unmonitored. Track unit cost per use case from the first pilot.
- Single points of failure. Every route depends on one model or provider. Define fallbacks and test them.
- Pilots that never scale. A proof of concept built on exported data cannot be moved into production without redesign.
Where do the hardest design decisions get debated?
Questions such as how much inference to own, how to route by data class and how to satisfy supervisors across borders are rarely settled in a vendor presentation. Enterprise Private AI UAE 2027 in Dubai, on 17 to 18 March 2027, brings together technology, security and data leaders to compare how they are approaching exactly these choices across cloud, on-premises and edge.
Next steps for bank technology leaders
You do not need a complete target architecture to begin. You need a defensible sequence.
- Build the placement map. List current and planned AI use cases, classify their data, and assign a provisional venue using the table above as a template.
- Agree decision rights. Name who approves a use case, who owns its risk and who can stop it. Involve the CTO, CIO, CISO, compliance and the business owner together.
- Stand up one governed pathway. Choose a single medium-risk use case and deliver it through the full stack of gateway, controls, logging and monitoring. Reuse that pathway for the next use case.
- Test failure and exit. Simulate a provider outage and a data-handling incident, and confirm you can move a workload between venues.
- Brief your regulator relationships early. Share your approach with compliance and, where appropriate, supervisors before scale, not after.
If you want to test your plan against peers, review the summit programme and agenda to see which sessions address regulated-sector architecture.